Claude was the copilot for this post about my Techtonique python package mlreserving, and yes, we’re cooked :) (no, actually, we’ll have to be very smart, competent, and creative).
This post is a follow-up to ‘mlreserve: machine-learning loss reserving on ‘real-world’ triangles (based on a ‘ChainLadder’ fork)’, with better explanations of what’s being done; a better description of the experimental setting.
We simulate claims triangles whose true outstanding reserve is known, then ask how well two families of methods recover it:
- the Mack Chain-Ladder (
chainladder.MackChainladder), the actuarial benchmark; mlreserving.MLReserving(From Techtonique’s package mlreserving) wrapped around every scikit-learn regressor that can be built with default arguments (no tuning), with two feature sets.
The triangles are deliberately distorted in two ways that break the chain-ladder assumptions: settlement speed-up (recent accident years pay faster) and a calendar-year inflation shock (payments made after a given calendar period grow faster). Section 1 states the setting formally, Section 2 makes the two distortions visible, Section 3 runs the model sweep.
⚠️ Deliberate data leakage. Models are selected on the truth of the evaluation triangles. Section 3.4 re-scores the selected models on fresh triangles, and Section 4 discusses what that check does and does not prove.
1. Formal setting
1.1 Notation
A run-off triangle has accident (origin) years \(i = 1,\dots,n\) and development years \(j = 1,\dots,n\), with \(n = 10\).
The calendar period of cell \((i,j)\) is
\[t = i + j - 1 .\]Let \(X_{ij}\) be the incremental payment of accident year \(i\) in development year \(j\), and \(C_{ij} = \sum_{k \le j} X_{ik}\) the cumulative payment. Only cells with \(t \le n\) are observed:
\[\mathcal{D} = \{X_{ij} : i + j - 1 \le n\} \quad \text{(upper triangle)}, \qquad \mathcal{F} = \{(i,j) : i + j - 1 > n\} \quad \text{(future cells)}.\]The true reserve of accident year \(i\) and the total reserve are
\[R_i = \sum_{j:\,(i,j)\in\mathcal{F}} X_{ij}, \qquad R = \sum_{i=2}^{n} R_i .\]Because we simulate the full \(n \times n\) square, \(R\) is known exactly for every triangle (no tail beyond \(j = n\)).
1.2 Data-generating process (aggregate simulator)
The expected incremental payment factorises into an ultimate, a payment pattern and a calendar index:
\[\boxed{\;\mu_{ij} \;=\; U_i \cdot \pi_{ij} \cdot I_{t}\;}, \qquad t = i+j-1 .\]Ultimates (exposure). A 3% per year volume trend with lognormal noise:
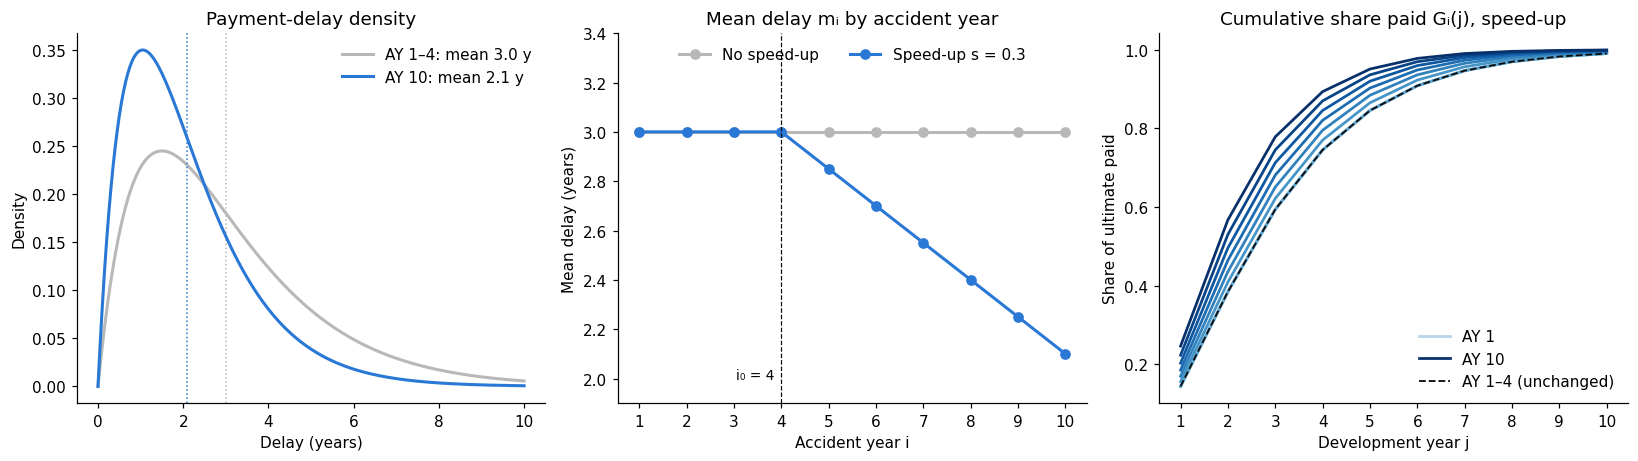
\[U_i = 50\,000\,\bigl(1 + 0.03\,(i-1)\bigr)\,e^{\varepsilon_i}, \qquad \varepsilon_i \overset{iid}{\sim} \mathcal{N}(0,\,0.05^2).\]Payment pattern and settlement speed-up. The payment delay of a claim from accident year \(i\) is \(\mathrm{Gamma}(\kappa = 2,\ \theta_i = m_i/\kappa)\), with mean delay \(m_i\) (in years). Development year \(j\) collects the payments falling in \((j-1, j]\):
\[\pi_{ij} = G_i(j) - G_i(j-1), \qquad G_i = \text{c.d.f. of } \mathrm{Gamma}(2,\ m_i/2).\]The speed-up shortens the mean delay linearly for accident years after \(i_0 = 4\):
\[m_i \;=\; m_0\Bigl(1 - s\,\Bigl(\tfrac{i - i_0}{\,n - i_0\,}\Bigr)_{+}\Bigr), \qquad m_0 = 3,\ \ i_0 = 4,\ \ (x)_+ = \max(x,0).\]So accident years 1–4 share the same pattern, and the mean delay then falls linearly to \(m_0(1-s)\) for the latest year: with \(s = 0.3\), from 3 years to 2.1 years. (Truncating at \(j = n\) drops at most about 1% of the mass, for the slowest years.)
Calendar-year inflation. A 2% per period trend up to calendar period \(\tau = 7\), then growth at rate \(g\):
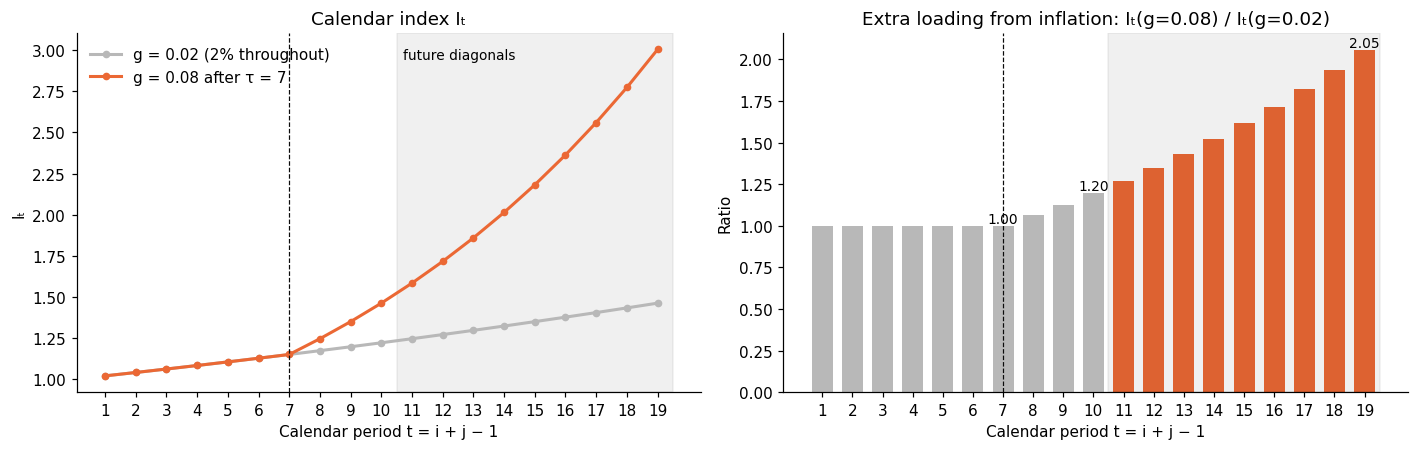
\[I_t = \exp\bigl(0.02\,\min(t, \tau) \;+\; g\,(t - \tau)_{+}\bigr), \qquad \tau = 7 .\]With \(g = 0.02\) this is a plain 2% trend. With \(g = 0.08\) there is a kink at \(t = 7\). Only three observed diagonals (\(t = 8, 9, 10\)) carry the higher rate, while every future diagonal (\(t = 11,\dots,19\)) does, up to \(I_{19}/I_{19}^{(g=0.02)} = e^{0.06 \times 12} \approx 2.05\).
Noise (over-dispersed Poisson). With dispersion \(\varphi = 5\),
\[X_{ij} = \varphi\, N_{ij}, \qquad N_{ij} \sim \mathrm{Poisson}(\mu_{ij}/\varphi) \quad\Longrightarrow\quad \mathbb{E}[X_{ij}] = \mu_{ij}, \quad \mathrm{Var}[X_{ij}] = \varphi\,\mu_{ij}.\]Scenarios.
| Scenario | speed-up \(s\) | post-\(\tau\) inflation \(g\) |
|---|---|---|
| Baseline (control, used for illustration only) | 0 | 0.02 |
| Inflation only (illustration only) | 0 | 0.08 |
| Settlement speed-up | 0.3 | 0.02 |
| Speed-up + inflation | 0.3 | 0.08 |
We also use two triangles aggregated from the Wang & Wüthrich individual-claims simulator (“Speed-up”, and “All combined” = speed-up + inflation shock + a few large, slowly paid claims). Their generating process is richer than the one above and is not restated here.
1.3 Why these distortions break the Chain-Ladder hypotheses
The Chain-Ladder estimates volume-weighted age-to-age factors from the observed triangle,
\[\hat f_j = \frac{\sum_{i=1}^{n-j} C_{i,j+1}}{\sum_{i=1}^{n-j} C_{ij}}, \qquad \hat C_{in} = C_{i,n+1-i}\prod_{j=n+1-i}^{n-1}\hat f_j, \qquad \hat R_i^{\,CL} = \hat C_{in} - C_{i,n+1-i},\]and is unbiased when the expected development ratio \(\mathbb{E}[C_{i,j+1}]/\mathbb{E}[C_{ij}]\) does not depend on \(i\). Under our DGP (ignoring noise),
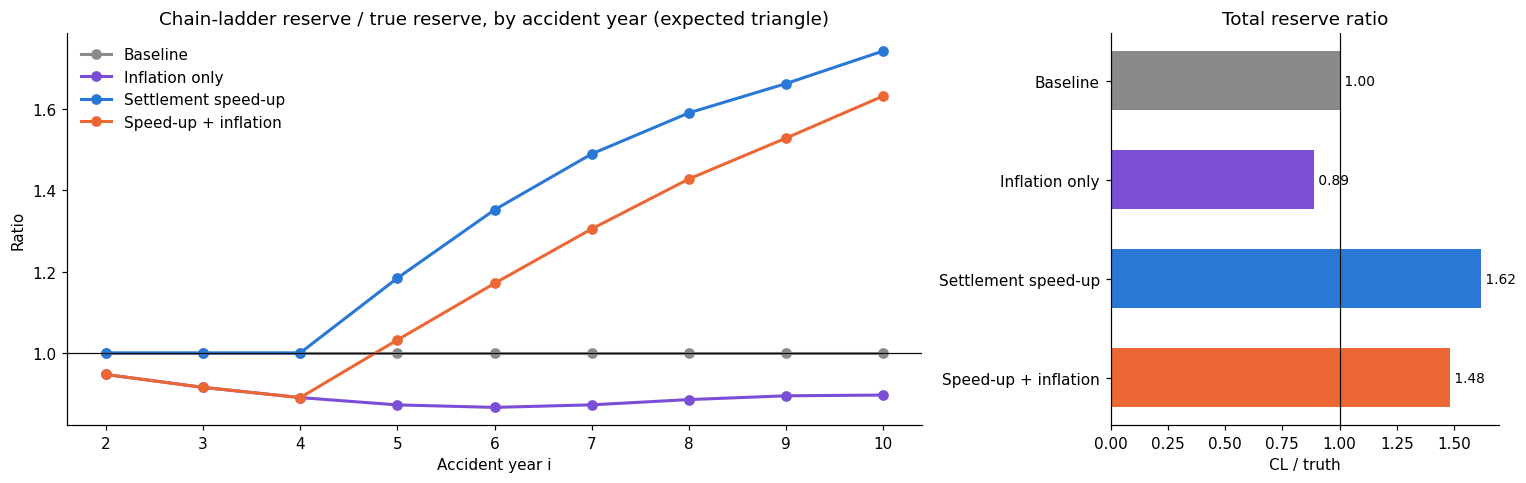
\[\frac{\mathbb{E}[C_{i,j+1}]}{\mathbb{E}[C_{ij}]} = \frac{\sum_{k\le j+1}\pi_{ik}\,I_{i+k-1}}{\sum_{k\le j}\pi_{ik}\,I_{i+k-1}} .\]- Baseline (\(s=0\), constant 2% trend). \(\pi_{ik}\) does not depend on \(i\), and \(I_{i+k-1} = e^{0.02(i-1)}e^{0.02k}\) is separable, so the \(i\)-terms cancel and the Chain-Ladder is exactly right in expectation.
- Speed-up. \(\pi_{ik}\) depends on \(i\). Recent accident years are more developed at a given age than the older years the factors \(\hat f_j\) are estimated from. Applying those slow factors to fast years overstates the reserve.
- Inflation kink. \(I_{i+k-1}\) is no longer separable in \((i,k)\). Future diagonals grow at \(g\), while the factors mostly reflect the 2% regime. On its own this understates the reserve, so it partly offsets the speed-up.
1.4 The machine-learning reserving model
mlreserving regresses the arcsinh-transformed incremental payments on features of the cell:
with either
[log]features: \(\mathbf{x}_{ij} = (\log i,\ \log j)\), standardised; or[onehot]features: \(\mathbf{x}_{ij} = (\mathbf{e}_i,\ \mathbf{e}_j)\), one-hot origin and development dummies.
No calendar feature is used. Any regressor \(\hat f\) gives a reserve by back-transforming the predictions of the future cells:
\[\hat R_i = \sum_{j:\,(i,j)\in\mathcal{F}} \sinh\bigl(\hat f(\mathbf{x}_{ij})\bigr), \qquad \hat R = \sum_i \hat R_i .\]1.5 Evaluation and the selection step
For each triangle \(k\) we record the relative error of the total reserve, \(e_k = \hat R_k / R_k - 1\).
For a block \(b\) of triangles (a scenario, or a single Wang & Wüthrich triangle),
\[\mathrm{relRMSE}_b(m) = \Bigl(\tfrac{1}{|b|}\sum_{k\in b} e_k(m)^2\Bigr)^{1/2}, \qquad \mathrm{Score}(m) = \tfrac{1}{4}\sum_{b} \mathrm{relRMSE}_b(m),\]over the four blocks: two simulated scenarios with 20 triangles each, plus the two Wang & Wüthrich triangles.
We keep the top \(K = 5\) models using the true reserves of the very triangles we report on. For the selected models, \(\mathrm{Score}(\hat m;\mathcal{D}_{\text{sel}})\) is an optimistically biased estimate of the risk, because \(\mathbb{E}\bigl[\min_m \widehat{\mathrm{Score}}(m)\bigr] \le \min_m \mathbb{E}\bigl[\widehat{\mathrm{Score}}(m)\bigr]\). Section 3.4 re-scores \(\widehat{\mathcal{M}}\) on \(\mathcal{D}_{\text{fresh}}\), new seeds from the same generator.
0. Setup
%pip install -q mlreserving chainladder scikit-learn matplotlib joblib scipy pandas
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m79.5/79.5 kB[0m [31m1.0 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m2.3/2.3 MB[0m [31m28.5 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m10.8/10.8 MB[0m [31m43.2 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m155.3/155.3 kB[0m [31m5.2 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m257.5/257.5 kB[0m [31m11.7 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m4.9/4.9 MB[0m [31m37.9 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m86.2/86.2 kB[0m [31m5.0 MB/s[0m eta [36m0:00:00[0m
[2K [90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━[0m [32m800.1/800.1 kB[0m [31m15.8 MB/s[0m eta [36m0:00:00[0m
[?25h[31mERROR: pip's dependency resolver does not currently take into account all the packages that are installed. This behaviour is the source of the following dependency conflicts.
google-colab 1.0.0 requires pandas==2.2.3, but you have pandas 3.0.6 which is incompatible.[0m[31m
[0m
import os
import time
import warnings

import chainladder as cl
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from joblib import Parallel, delayed
from matplotlib.colors import TwoSlopeNorm
from mlreserving import MLReserving
from scipy.stats import gamma
from sklearn.base import clone
from sklearn.utils import all_estimators

warnings.filterwarnings("ignore")
os.environ["PYTHONWARNINGS"] = "ignore"        # also silences joblib workers
pd.set_option("display.width", 160)
plt.rcParams.update({"figure.dpi": 110, "axes.spines.top": False,
                     "axes.spines.right": False, "font.size": 10})

n = 10                       # triangle size
BASE_YEAR = 2000             # chainladder needs calendar-like origins
TAU = 7                      # calendar period where the inflation regime changes
M0, I0, KAPPA = 3.0, 4, 2.0  # base mean delay, first sped-up AY, gamma shape
PHI = 5                      # ODP dispersion
N_REP = 20                   # triangles per scenario
SELECT_SEEDS = range(1, N_REP + 1)
FRESH_SEEDS = range(101, 101 + N_REP)
TOP_K = 5
N_JOBS = -1

SCENARIOS = {                # used in the benchmark
    "Settlement speed-up":  dict(speedup=0.3, inflation=0.02),
    "Speed-up + inflation": dict(speedup=0.3, inflation=0.08),
}
ILLUSTRATE = {               # used only in Section 2
    "Baseline":             dict(speedup=0.0, inflation=0.02),
    "Inflation only":       dict(speedup=0.0, inflation=0.08),
    **SCENARIOS,
}
INK, GREY, ACCENT, MACK_C = "#0b0b0b", "#b8b8b8", "#1baf7a", "#eb6834"
SCEN_COLOURS = {"Baseline": "#8a8a8a", "Inflation only": "#7a4fd6",
                "Settlement speed-up": "#2a78d6", "Speed-up + inflation": "#eb6834"}
Data-generating process
dgp_components returns the deterministic pieces of Section 1.2: \(m_i\), \(\pi_{ij}\), \(I_t\) and \(\mu_{ij}\), with \(\varepsilon_i = 0\).
simulate_case adds the lognormal ultimate noise and the over-dispersed Poisson noise.
AY = np.arange(1, n + 1)
DEV = np.arange(1, n + 1)
CAL = np.add.outer(AY, DEV) - 1                     # t = i + j - 1
FUTURE = CAL > n


def mean_delay(speedup):
    return M0 * (1 - speedup * np.maximum(0, (AY - I0) / (n - I0)))


def pattern(speedup):
    m = mean_delay(speedup)
    return np.array([np.diff(gamma.cdf(np.arange(n + 1), a=KAPPA, scale=mi / KAPPA))
                     for mi in m])                   # pi_ij


def inflation_index(g, t=CAL):
    return np.exp(0.02 * np.minimum(t, TAU) + g * np.maximum(t - TAU, 0))


def dgp_components(speedup, inflation, eps=None):
    eps = np.zeros(n) if eps is None else eps
    U = 5e4 * (1 + 0.03 * (AY - 1)) * np.exp(eps)
    pi = pattern(speedup)
    I = inflation_index(inflation)
    return dict(m=mean_delay(speedup), U=U, pi=pi, I=I, mu=U[:, None] * pi * I)


def make_case(full):
    full = np.asarray(full, dtype=float)
    cum = np.where(FUTURE, np.nan, np.cumsum(np.where(FUTURE, 0, full), axis=1))
    i, j = np.indices((n, n))
    long = pd.DataFrame({"origin": i.ravel() + 1, "dev": j.ravel() + 1,
                         "values": cum.ravel()}).dropna()
    long["development"] = long["origin"] + long["dev"] - 1
    cl_df = long.assign(origin=long["origin"] + BASE_YEAR,
                        development=long["development"] + BASE_YEAR)
    tri = cl.Triangle(cl_df, origin="origin", development="development",
                      columns="values", cumulative=True)
    return {"full": full, "upper_long": long[["origin", "development", "values"]],
            "upper_cl": tri, "true_total": float((full * FUTURE).sum())}


def simulate_case(seed, speedup=0.3, inflation=0.08, phi=PHI):
    rng = np.random.default_rng(seed)
    eps = rng.normal(0, 0.05, n)
    mu = dgp_components(speedup, inflation, eps)["mu"]
    return make_case(phi * rng.poisson(mu / phi))
2. Making the distortions visible
2.1 Settlement speed-up: payment delays and patterns
Left: the delay density \(\mathrm{Gamma}(2, m_i/2)\) for the slowest and fastest accident years. Middle: the mean delay \(m_i\) by accident year. Right: the cumulative share paid, \(G_i(j)\), by development year. Each curve is an accident year, and darker means more recent. Recent years under speed-up are further along at every age. The Chain-Ladder averages the old, slow curves.
s = SCENARIOS["Settlement speed-up"]["speedup"]
fig, axes = plt.subplots(1, 3, figsize=(15, 4.3))

x = np.linspace(0, 10, 400)
for mi, lab, col in [(M0, f"AY 1–{I0}: mean {M0:.1f} y", GREY),
                     (M0 * (1 - s), f"AY {n}: mean {M0*(1-s):.1f} y", SCEN_COLOURS["Settlement speed-up"])]:
    axes[0].plot(x, gamma.pdf(x, a=KAPPA, scale=mi / KAPPA), lw=2, color=col, label=lab)
    axes[0].axvline(mi, color=col, lw=1, ls=":")
axes[0].set(title="Payment-delay density", xlabel="Delay (years)", ylabel="Density")
axes[0].legend(frameon=False)

axes[1].plot(AY, mean_delay(0), "o-", color=GREY, lw=2, label="No speed-up")
axes[1].plot(AY, mean_delay(s), "o-", color=SCEN_COLOURS["Settlement speed-up"], lw=2,
             label=f"Speed-up s = {s}")
axes[1].axvline(I0, color=INK, lw=0.8, ls="--")
axes[1].annotate(f"i₀ = {I0}", (I0 - 0.15, 2.0), ha="right", fontsize=9)
axes[1].set(title="Mean delay mᵢ by accident year", xlabel="Accident year i",
            ylabel="Mean delay (years)", xticks=AY, ylim=(1.9, 3.4))
axes[1].legend(frameon=False, loc="upper center", ncol=2)

cum = np.cumsum(pattern(s), axis=1)
cmap = plt.cm.Blues(np.linspace(0.3, 1, n))
for i in range(n):
    axes[2].plot(DEV, cum[i], color=cmap[i], lw=1.8, label=f"AY {i+1}" if i in (0, n - 1) else None)
axes[2].plot(DEV, np.cumsum(pattern(0), axis=1)[0], color=INK, lw=1.2, ls="--",
             label="AY 1–4 (unchanged)")
axes[2].set(title="Cumulative share paid Gᵢ(j), speed-up", xlabel="Development year j",
            ylabel="Share of ultimate paid", xticks=DEV)
axes[2].legend(frameon=False, loc="lower right")
fig.tight_layout(); plt.show()

print("Share paid by end of development year 1 and 2, AY 1 vs AY 10:")
print(pd.DataFrame(cum[[0, -1], :2], index=["AY 1", "AY 10"], columns=["j=1", "j=2"]).round(3))
Share paid by end of development year 1 and 2, AY 1 vs AY 10:
         j=1    j=2
AY 1   0.144  0.385
AY 10  0.247  0.568
2.2 Calendar-year inflation: the index \(I_t\)
The shaded area is the future (calendar periods \(t > n\)), where the reserve sits. With \(g = 0.08\) the kink at \(\tau = 7\) leaves only three observed diagonals in the new regime. The right panel is the ratio of the two indices, which is the extra loading that inflation puts on each calendar period.
t = np.arange(1, 2 * n)
fig, axes = plt.subplots(1, 2, figsize=(13, 4.2))
for g, col, lab in [(0.02, GREY, "g = 0.02 (2% throughout)"),
                    (0.08, SCEN_COLOURS["Speed-up + inflation"], "g = 0.08 after τ = 7")]:
    axes[0].plot(t, inflation_index(g, t), "o-", ms=4, lw=2, color=col, label=lab)
ratio = inflation_index(0.08, t) / inflation_index(0.02, t)
axes[1].bar(t, ratio, color=np.where(t > n, SCEN_COLOURS["Speed-up + inflation"], GREY), width=0.7)
for ax in axes:
    ax.axvspan(n + 0.5, 2 * n - 0.5, color=INK, alpha=0.06)
    ax.axvline(TAU, color=INK, lw=0.8, ls="--")
    ax.set_xticks(t)
    ax.set_xlabel("Calendar period t = i + j − 1")
axes[0].text(n + 0.7, axes[0].get_ylim()[1] * 0.97, "future diagonals", va="top", fontsize=9)
axes[0].set(title="Calendar index Iₜ", ylabel="Iₜ")
axes[0].legend(frameon=False, loc="upper left")
axes[1].set(title="Extra loading from inflation: Iₜ(g=0.08) / Iₜ(g=0.02)", ylabel="Ratio")
for tt, r in zip(t, ratio):
    if tt in (TAU, n, 2 * n - 1):
        axes[1].annotate(f"{r:.2f}", (tt, r), ha="center", va="bottom", fontsize=9)
fig.tight_layout(); plt.show()
2.3 Where each distortion hits the triangle
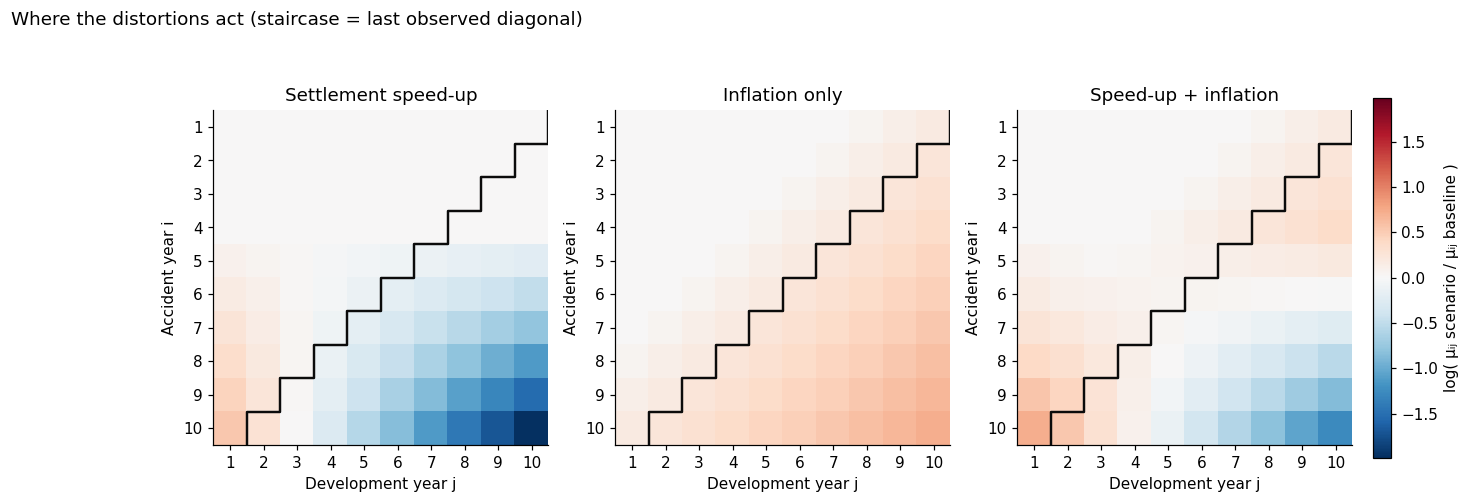
Each heatmap shows \(\log\bigl(\mu_{ij}^{\text{scenario}} / \mu_{ij}^{\text{baseline}}\bigr)\) cell by cell. Blue means less expected payment than the baseline and red means more. The staircase marks the boundary between the observed upper triangle and the future cells.
- Speed-up moves payments of recent accident years to earlier development years: red on the left, blue on the right. The blue cells are almost all in the future, which is the part Chain-Ladder overstates.
- Inflation loads the bottom-right diagonals and leaves the observed upper triangle almost untouched.
base_mu = dgp_components(**ILLUSTRATE["Baseline"])["mu"]
names = ["Settlement speed-up", "Inflation only", "Speed-up + inflation"]
logr = {k: np.log(dgp_components(**ILLUSTRATE[k])["mu"] / base_mu) for k in names}
lim = max(np.abs(v).max() for v in logr.values())
norm = TwoSlopeNorm(vmin=-lim, vcenter=0, vmax=lim)

fig, axes = plt.subplots(1, 3, figsize=(16, 5))
for ax, k in zip(axes, names):
    im = ax.imshow(logr[k], cmap="RdBu_r", norm=norm, origin="upper",
                   extent=(0.5, n + 0.5, n + 0.5, 0.5))
    # staircase: right edge of the last observed cell j = n + 1 - i in each row
    xs, ys = [], []
    for i in range(1, n + 1):
        xs += [n + 1.5 - i, n + 1.5 - i]
        ys += [i - 0.5, i + 0.5]
    ax.plot(xs, ys, color=INK, lw=1.6)
    ax.set(title=k, xlabel="Development year j", ylabel="Accident year i",
           xticks=DEV, yticks=AY)
cbar = fig.colorbar(im, ax=axes, shrink=0.85, pad=0.015)
cbar.set_label("log( μᵢⱼ scenario / μᵢⱼ baseline )")
fig.suptitle("Where the distortions act (staircase = last observed diagonal)", x=0.01, ha="left")
plt.show()
2.4 What this does to the Chain-Ladder, without noise
We feed the expected triangle \(\mu_{ij}\) (no noise, \(\varepsilon_i = 0\)) to the chain-ladder formulas of Section 1.3 and compare the resulting reserve with the true expected reserve \(\sum_{(i,j)\in\mathcal F}\mu_{ij}\). This isolates the structural bias of Chain-Ladder in each scenario. In the baseline the ratio is exactly 1, as Section 1.3 predicts.
def expected_cl_vs_truth(speedup, inflation):
    mu = dgp_components(speedup, inflation)["mu"]
    C = np.cumsum(mu, axis=1)
    f = np.array([C[: n - j - 1, j + 1].sum() / C[: n - j - 1, j].sum() for j in range(n - 1)])
    latest = np.array([C[i, n - 1 - i] for i in range(n)])
    cl_ult = np.array([latest[i] * np.prod(f[n - 1 - i:]) for i in range(n)])
    return cl_ult - latest, (mu * FUTURE).sum(axis=1)


fig, axes = plt.subplots(1, 2, figsize=(14, 4.5), gridspec_kw={"width_ratios": [2.2, 1]})
totals = {}
for k, par in ILLUSTRATE.items():
    cl_res, true_res = expected_cl_vs_truth(**par)
    axes[0].plot(AY[1:], cl_res[1:] / true_res[1:], "o-", lw=2, color=SCEN_COLOURS[k], label=k)
    totals[k] = cl_res.sum() / true_res.sum()
axes[0].axhline(1, color=INK, lw=0.8)
axes[0].set(title="Chain-ladder reserve / true reserve, by accident year (expected triangle)",
            xlabel="Accident year i", ylabel="Ratio", xticks=AY[1:])
axes[0].legend(frameon=False)
k = list(totals)
axes[1].barh(k[::-1], [totals[x] for x in k[::-1]], color=[SCEN_COLOURS[x] for x in k[::-1]], height=0.6)
axes[1].axvline(1, color=INK, lw=0.8)
for y, x in enumerate(k[::-1]):
    axes[1].annotate(f" {totals[x]:.2f}", (totals[x], y), va="center", fontsize=9)
axes[1].set(title="Total reserve ratio", xlabel="CL / truth")
fig.tight_layout(); plt.show()
2.5 From expectations to simulated triangles: the spread of the truth and of Mack
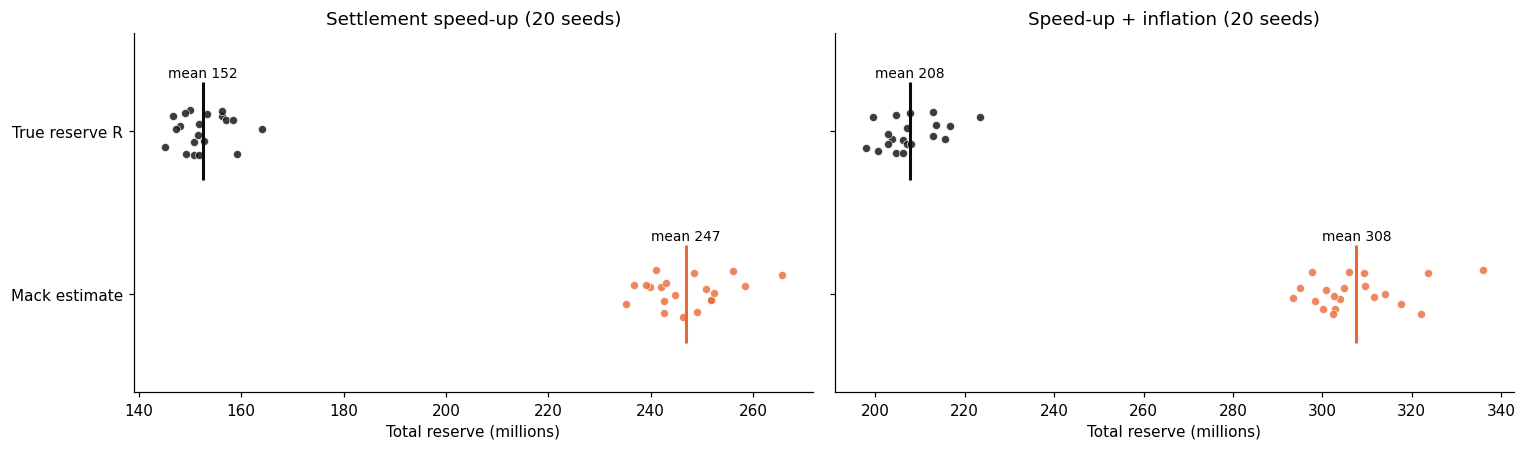
With noise added, each scenario gives a distribution of true total reserves \(R\) over seeds. Below, for the 20 selection seeds of each benchmark scenario, are the true total reserves (black) and the Mack estimates (orange). The gap between the two clouds is the chain-ladder bias, and it is much larger than the seed-to-seed noise.
fig, axes = plt.subplots(1, 2, figsize=(14, 4.2), sharey=True)
rng = np.random.default_rng(0)
for ax, (sc, par) in zip(axes, SCENARIOS.items()):
    cases = [simulate_case(seed, **par) for seed in SELECT_SEEDS]
    truth = np.array([c["true_total"] for c in cases]) / 1000
    mack = np.array([float(cl.MackChainladder().fit(c["upper_cl"]).ibnr_.sum()) for c in cases]) / 1000
    for y, vals, col, lab in [(1, truth, INK, "True reserve R"), (0, mack, MACK_C, "Mack estimate")]:
        ax.scatter(vals, y + rng.uniform(-0.15, 0.15, len(vals)), color=col, s=28, alpha=0.8,
                   edgecolor="white", linewidth=0.5)
        ax.vlines(vals.mean(), y - 0.3, y + 0.3, color=col, lw=2)
        ax.annotate(f"mean {vals.mean():,.0f}", (vals.mean(), y + 0.33), ha="center", fontsize=9)
    ax.set_yticks([0, 1], ["Mack estimate", "True reserve R"])
    ax.set(title=f"{sc} ({N_REP} seeds)", xlabel="Total reserve (millions)", ylim=(-0.6, 1.6))
fig.tight_layout(); plt.show()
3. The benchmark: untuned scikit-learn regressors in mlreserving
3.1 Evaluation triangles
squares = {
    "Speed-up": [4172.1, 16153.4, 14800.2, 7561.1, 3275, 1856.3, 726.7, 410.7, 35.8, 140, 4983.2, 18064.1, 13574.5, 8350.7, 3954.9, 1499, 510.3, 9.5, 0, 11.3, 4698.1, 19428.8, 14864, 7343, 3710.5, 1378.6, 384.7, 92.2, 6.8, 27.1, 5467.1, 18481, 14847.6, 8089.7, 2794.1, 1379.2, 549.5, 152.2, 6.8, 0, 5985.2, 21516.6, 15980.6, 8353, 2954.2, 1655.5, 636.4, 191.3, 211.3, 28.9, 8274.1, 22014.4, 15981.4, 7425.8, 2362.7, 731, 242.1, 41.6, 52.8, 0, 8148.4, 24712.9, 16329.1, 6587.5, 2804.9, 753.6, 49.5, 0, 0, 0, 9974.2, 27573.4, 14523, 5141.6, 1123.8, 350, 73.3, 0, 0, 0, 10698.8, 29877.8, 14303.3, 3200.3, 978.3, 239.1, 0, 0, 0, 0, 13669.1, 30541.7, 10984, 1837.5, 157.3, 0, 0, 0, 0, 0],
    "All combined": [4236.8, 16766.9, 15671.5, 8229, 3582.8, 2143.9, 838.8, 548.6, 57.6, 261.6, 5195.7, 19008.8, 15926.9, 9857.6, 4643.8, 1746.5, 712.4, 26.4, 0, 22.5, 4956.8, 20861.6, 16283.4, 8704.2, 4321.7, 1876.2, 666.5, 161.8, 14.7, 61.4, 5908.2, 20336.4, 16580.1, 9331.1, 3673.8, 2276.2, 1205.8, 332.2, 15.4, 0, 6586.1, 24045.6, 18499, 11218.3, 4576, 3174.8, 1307, 460.6, 665, 96.3, 9292, 26084.3, 21055.7, 11396.7, 4203.8, 1531.8, 585.4, 115, 163.7, 0, 9702.9, 33010, 25202.7, 12133, 6404.4, 1956.8, 385.9, 0, 0, 0, 13752.5, 42686.8, 25857.7, 10698.4, 2706.5, 3213, 4232.5, 0, 0, 0, 17094.3, 53962.4, 30132.7, 8527.6, 3087.9, 746.2, 0, 0, 0, 0, 25375.8, 63473.7, 26195.3, 5737.2, 507, 674.2, 0, 0, 0, 0],
}


def build_cases(seeds):
    return [(sc, seed, simulate_case(seed, **par))
            for sc, par in SCENARIOS.items() for seed in seeds]


select_cases = build_cases(SELECT_SEEDS) + [
    (f"W&W: {k}", 0, make_case(np.reshape(v, (n, n)))) for k, v in squares.items()]
fresh_cases = build_cases(FRESH_SEEDS)
print(f"selection set: {len(select_cases)} triangles, fresh set: {len(fresh_cases)} triangles")
selection set: 42 triangles, fresh set: 40 triangles
3.2 Candidates and scoring
Every scikit-learn regressor that builds with default arguments, under both feature sets \(\times\) [log], [onehot].
Wrappers and multi-output-only estimators are excluded. A pair that errors or returns a non-finite reserve on any
triangle is dropped. Residuals are taken in-sample (residual_source="in_sample"); only point estimates are needed here.
EXCLUDE = {"CCA", "PLSCanonical", "IsotonicRegression", "MultiOutputRegressor",
           "RegressorChain", "StackingRegressor", "VotingRegressor",
           "MultiTaskElasticNet", "MultiTaskElasticNetCV", "MultiTaskLasso",
           "MultiTaskLassoCV", "TransformedTargetRegressor"}


def candidates():
    out = {}
    for name, Est in all_estimators(type_filter="regressor"):
        if name in EXCLUDE:
            continue
        try:
            est = Est()
        except Exception:
            continue
        if "random_state" in est.get_params():
            est.set_params(random_state=1)
        out[name] = est
    return out


def total_ibnr_ml(est, case, use_factors):
    m = MLReserving(model=clone(est), use_factors=use_factors,
                    residual_source="in_sample", random_state=1)
    m.fit(case["upper_long"], origin_col="origin", development_col="development",
          value_col="values", cumulated=True)
    m.predict()
    return float(m.get_ibnr().mean.sum())


def total_ibnr_mack(case):
    return float(cl.MackChainladder().fit(case["upper_cl"]).ibnr_.sum())


def score_one(label, est, use_factors, cases):
    import warnings; warnings.filterwarnings("ignore")
    rows = []
    for sc, seed, case in cases:
        try:
            pred = total_ibnr_mack(case) if est is None else total_ibnr_ml(est, case, use_factors)
        except Exception:
            return []
        if not np.isfinite(pred):
            return []
        rows.append({"model": label, "scenario": sc, "seed": seed,
                     "error": pred - case["true_total"],
                     "rel_error": pred / case["true_total"] - 1})
    return rows


def summarise(df):
    g = df.groupby(["model", "scenario"])
    s = g["error"].agg(bias="mean", RMSE=lambda e: np.sqrt(np.mean(e ** 2)))
    s["relRMSE"] = g["rel_error"].agg(lambda e: np.sqrt(np.mean(e ** 2)))
    return s.reset_index()


def pivot_rel(s):
    p = s.pivot(index="model", columns="scenario", values="relRMSE")
    p["mean relRMSE"] = p.mean(axis=1)
    return p.sort_values("mean relRMSE")


cands = candidates()
jobs = [("Mack Chain-Ladder", None, False)] + [
    (f"{name} [{'onehot' if f else 'log'}]", est, f)
    for name, est in cands.items() for f in (False, True)]
print(f"{len(jobs) - 1} (estimator, feature-set) pairs + Mack")
86 (estimator, feature-set) pairs + Mack
3.3 Sweep on the selection set (≈ 2–3 minutes on 2 cores)
t0 = time.time()
res = Parallel(n_jobs=N_JOBS)(delayed(score_one)(lbl, est, f, select_cases) for lbl, est, f in jobs)
sel = pd.DataFrame([r for rr in res for r in rr])
print(f"done in {time.time() - t0:.0f}s; {sel['model'].nunique() - 1} pairs ran without error")

sel_rank = pivot_rel(summarise(sel))
mack_rank = list(sel_rank.index).index("Mack Chain-Ladder") + 1
print(f"Mack Chain-Ladder rank: {mack_rank} / {len(sel_rank)}\n")
print("Relative RMSE of the total reserve (W&W columns are single triangles, i.e. |relative error|):")
sel_rank.round(3).head(20)
done in 516s; 82 pairs ran without error
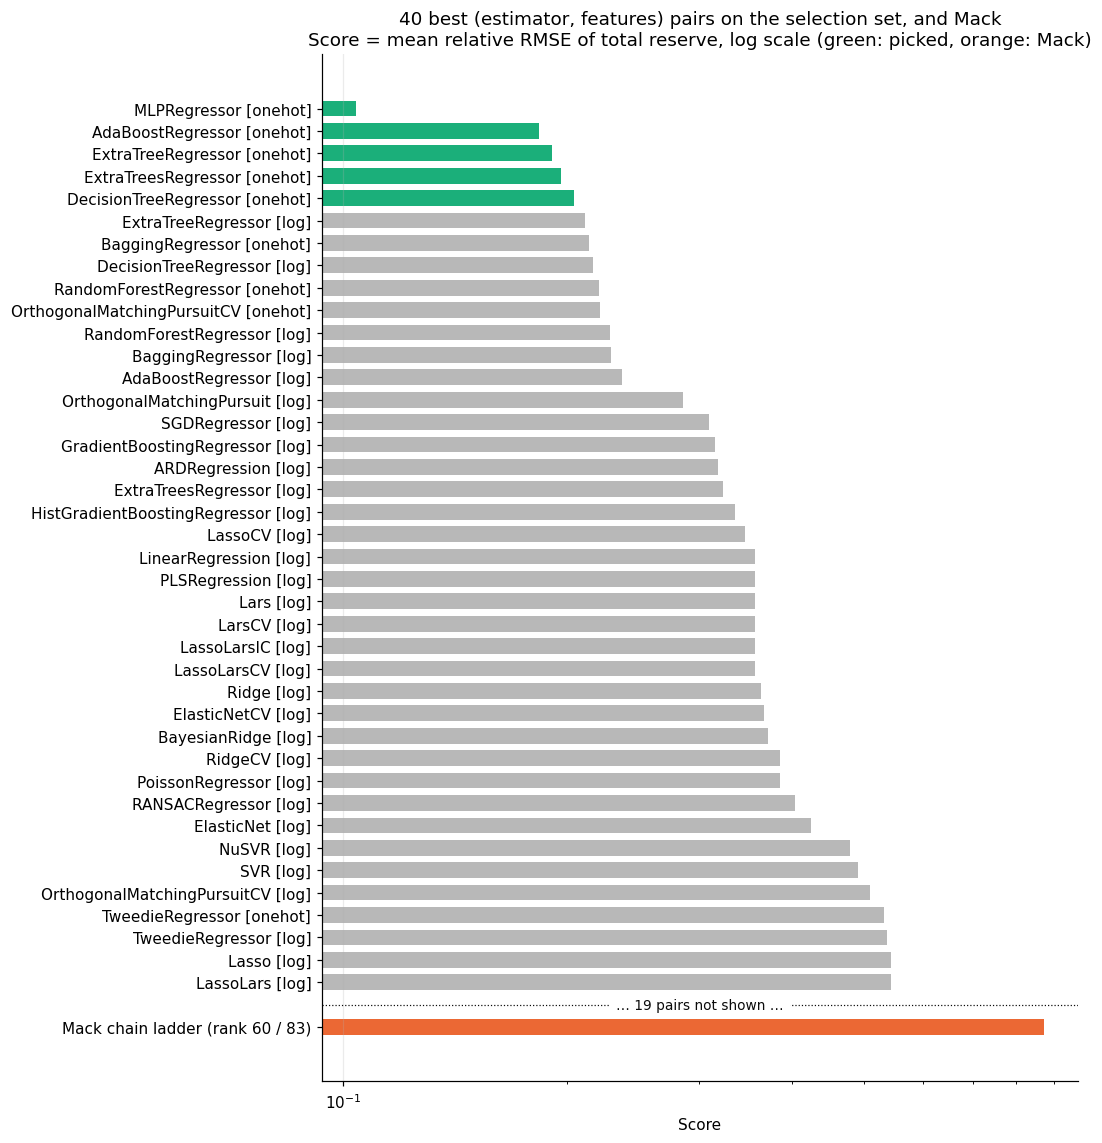
Mack Chain-Ladder rank: 60 / 83

Relative RMSE of the total reserve (W&W columns are single triangles, i.e. |relative error|):
| scenario | Settlement speed-up | Speed-up + inflation | W&W: All combined | W&W: Speed-up | mean relRMSE |
|---|---|---|---|---|---|
| model | |||||
| MLPRegressor [onehot] | 0.039 | 0.127 | 0.229 | 0.022 | 0.104 |
| AdaBoostRegressor [onehot] | 0.211 | 0.100 | 0.241 | 0.182 | 0.183 |
| ExtraTreeRegressor [onehot] | 0.139 | 0.069 | 0.159 | 0.395 | 0.191 |
| ExtraTreesRegressor [onehot] | 0.139 | 0.070 | 0.171 | 0.404 | 0.196 |
| DecisionTreeRegressor [onehot] | 0.140 | 0.069 | 0.176 | 0.430 | 0.204 |
| ExtraTreeRegressor [log] | 0.345 | 0.109 | 0.052 | 0.340 | 0.211 |
| BaggingRegressor [onehot] | 0.177 | 0.046 | 0.215 | 0.418 | 0.214 |
| DecisionTreeRegressor [log] | 0.137 | 0.337 | 0.052 | 0.340 | 0.217 |
| RandomForestRegressor [onehot] | 0.206 | 0.046 | 0.171 | 0.458 | 0.220 |
| OrthogonalMatchingPursuitCV [onehot] | 0.090 | 0.158 | 0.202 | 0.437 | 0.222 |
| RandomForestRegressor [log] | 0.190 | 0.142 | 0.183 | 0.397 | 0.228 |
| BaggingRegressor [log] | 0.194 | 0.128 | 0.185 | 0.408 | 0.229 |
| AdaBoostRegressor [log] | 0.178 | 0.138 | 0.069 | 0.561 | 0.237 |
| OrthogonalMatchingPursuit [log] | 0.067 | 0.168 | 0.590 | 0.317 | 0.286 |
| SGDRegressor [log] | 0.581 | 0.349 | 0.144 | 0.164 | 0.310 |
| GradientBoostingRegressor [log] | 0.212 | 0.155 | 0.376 | 0.520 | 0.316 |
| ARDRegression [log] | 0.655 | 0.425 | 0.192 | 0.003 | 0.319 |
| ExtraTreesRegressor [log] | 0.305 | 0.232 | 0.265 | 0.492 | 0.324 |
| HistGradientBoostingRegressor [log] | 0.532 | 0.281 | 0.005 | 0.525 | 0.336 |
| LassoCV [log] | 0.677 | 0.432 | 0.174 | 0.104 | 0.347 |
picks = [m for m in sel_rank.index if m != "Mack Chain-Ladder"][:TOP_K]
print("Picked:", picks)

# Top 40 pairs, plus Mack appended below a gap if it ranks outside the top 40
TOP_N = 40
score = sel_rank["mean relRMSE"]
top = score.head(TOP_N)
labels = list(top.index)
values = list(top.values)
ypos = list(range(len(labels)))
if "Mack Chain-Ladder" not in top.index:
    labels.append(f"Mack Chain-Ladder (rank {mack_rank} / {len(score)})")
    values.append(score["Mack Chain-Ladder"])
    ypos.append(len(top) + 1)                    # leave one empty row as a gap
colors = [MACK_C if m.startswith("Mack") else ACCENT if m in picks else GREY for m in labels]

fig, ax = plt.subplots(figsize=(10, 10.5))
ax.barh(ypos, values, color=colors, height=0.7)
ax.set_yticks(ypos, labels)
ax.invert_yaxis()
if ypos[-1] > len(top):
    ax.axhline(len(top), color=INK, lw=0.8, ls=":")
    ax.annotate(f"… {mack_rank - TOP_N - 1} pairs not shown …", (0.5, len(top)),
                xycoords=("axes fraction", "data"), ha="center", va="center",
                fontsize=9, color=INK, backgroundcolor="white")
ax.set_xscale("log")
ax.set(title=f"{TOP_N} best (estimator, features) pairs on the selection set, and Mack\n"
             "Score = mean relative RMSE of total reserve, log scale (green: picked, orange: Mack)",
       xlabel="Score")
ax.grid(axis="x", alpha=0.25)
fig.tight_layout(); plt.show()
Picked: ['MLPRegressor [onehot]', 'AdaBoostRegressor [onehot]', 'ExtraTreeRegressor [onehot]', 'ExtraTreesRegressor [onehot]', 'DecisionTreeRegressor [onehot]']
3.4 Re-scoring the picks on fresh triangles
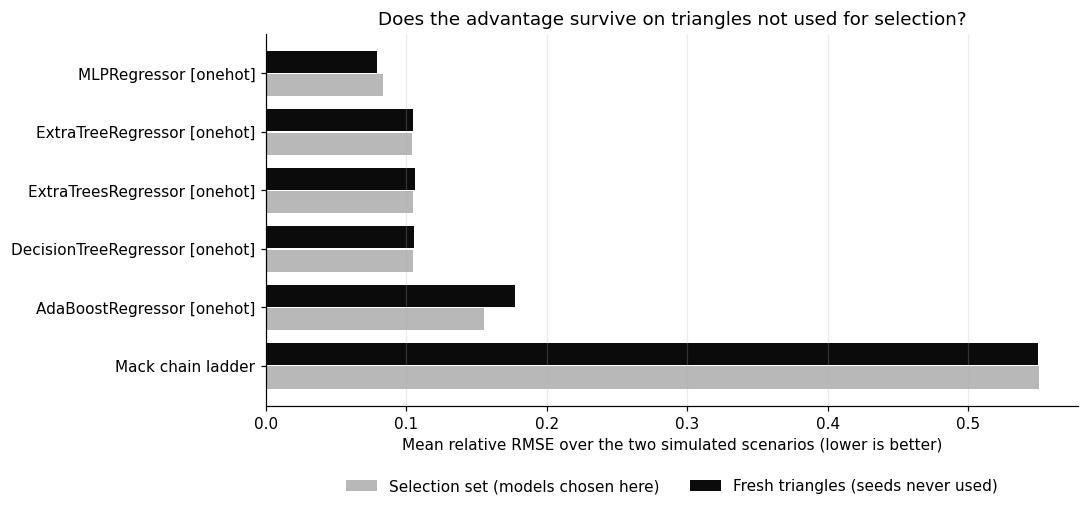
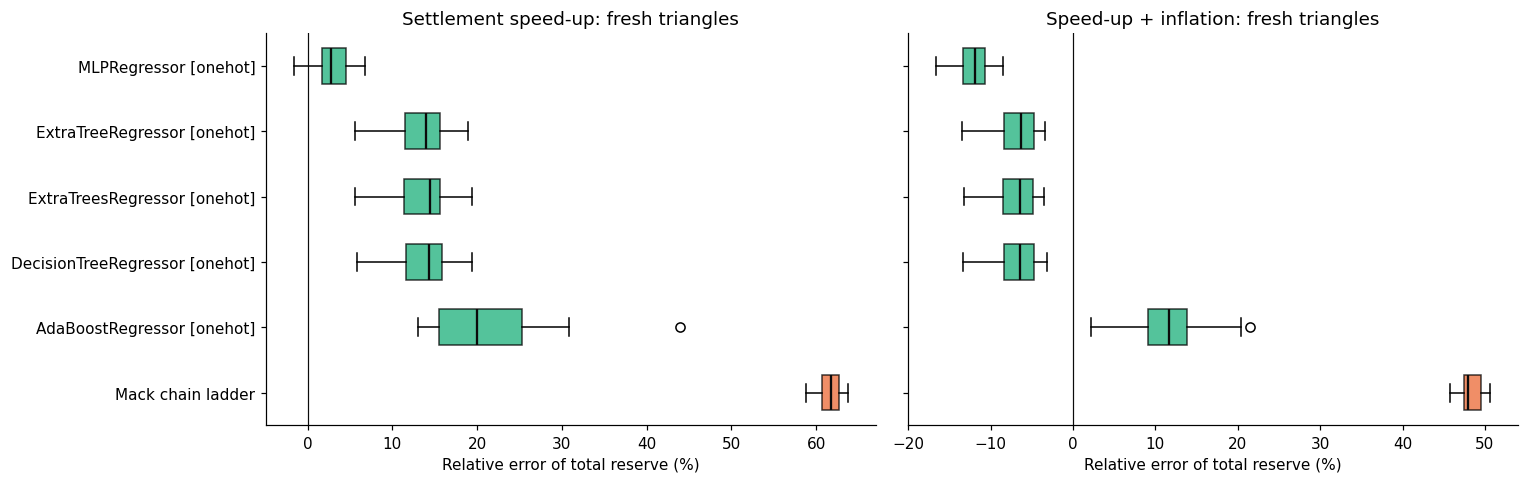
These are new seeds (101–120) from the same two scenarios. No model was selected on them.
pick_jobs = [j for j in jobs if j[0] in picks or j[0] == "Mack Chain-Ladder"]
res = Parallel(n_jobs=N_JOBS)(delayed(score_one)(lbl, est, f, fresh_cases) for lbl, est, f in pick_jobs)
fresh = pd.DataFrame([r for rr in res for r in rr])
fresh_rank = pivot_rel(summarise(fresh))

sim_cols = list(SCENARIOS)
compare = pd.DataFrame({
    "selection set": sel_rank.loc[picks + ["Mack Chain-Ladder"], sim_cols].mean(axis=1),
    "fresh triangles": fresh_rank.loc[picks + ["Mack Chain-Ladder"], "mean relRMSE"],
}).sort_values("selection set")

fig, ax = plt.subplots(figsize=(10, 4.8))
y = np.arange(len(compare))
ax.barh(y + 0.2, compare["selection set"], height=0.38, color=GREY, label="Selection set (models chosen here)")
ax.barh(y - 0.2, compare["fresh triangles"], height=0.38, color=INK, label="Fresh triangles (seeds never used)")
ax.set_yticks(y, compare.index); ax.invert_yaxis()
ax.set(title="Does the advantage survive on triangles not used for selection?",
       xlabel="Mean relative RMSE over the two simulated scenarios (lower is better)")
ax.legend(frameon=False, loc="upper center", bbox_to_anchor=(0.5, -0.16), ncol=2)
ax.grid(axis="x", alpha=0.25)
fig.tight_layout(); plt.show()
compare.round(3)
| selection set | fresh triangles | |
|---|---|---|
| model | ||
| MLPRegressor [onehot] | 0.083 | 0.079 |
| ExtraTreeRegressor [onehot] | 0.104 | 0.105 |
| ExtraTreesRegressor [onehot] | 0.105 | 0.106 |
| DecisionTreeRegressor [onehot] | 0.105 | 0.105 |
| AdaBoostRegressor [onehot] | 0.155 | 0.177 |
| Mack Chain-Ladder | 0.551 | 0.549 |
# Error distribution of the picks vs Mack on the fresh triangles
fig, axes = plt.subplots(1, 2, figsize=(14, 4.5), sharey=True)
order = list(compare.index)
for ax, sc in zip(axes, SCENARIOS):
    d = fresh[fresh["scenario"] == sc]
    data = [d.loc[d["model"] == m, "rel_error"].values * 100 for m in order]
    bp = ax.boxplot(data, vert=False, widths=0.55, patch_artist=True,
                    medianprops=dict(color=INK, lw=1.5))
    for patch, m in zip(bp["boxes"], order):
        patch.set_facecolor(MACK_C if m == "Mack Chain-Ladder" else ACCENT)
        patch.set_alpha(0.75)
    ax.axvline(0, color=INK, lw=0.8)
    ax.set_yticks(range(1, len(order) + 1), order)
    ax.set(title=f"{sc}: fresh triangles", xlabel="Relative error of total reserve (%)")
axes[0].invert_yaxis()
fig.tight_layout(); plt.show()
4. Reading the results
- Chain-Ladder. As Section 2.4 predicts, the speed-up makes Mack over-reserve heavily. The inflation kink pulls the other way but only partly offsets it, so Mack sits near the bottom of the ranking in both scenarios.
- What “works”. The top of the ranking is dominated by
[onehot]features. Origin dummies let a learner absorb part of the speed-up as an accident-year effect, and non-linear learners (MLP, trees) are not tied to the multiplicative origin × development structure that the Chain-Ladder shares with linear models. - What the fresh-seed check shows. The scores of the picks barely move on new seeds, so the selection is not overfitting individual seeds. It is not evidence that the selection generalises. The fresh triangles come from the same generator with the same \(s\), \(g\), \(\tau\) and \(i_0\). Selecting on the truth tuned the model choice to these distortions. A fair test would change the data-generating process: no distortion (the Baseline), a slow-down (\(s < 0\)), a different \(\tau\), or the individual-claims simulator with other settings.
- Where the picks still miss. In the boxplot of Section 3.4, the learners over-reserve under speed-up alone and under-reserve once inflation is added. None of them sees a calendar feature, so the future growth of \(I_t\) (Section 2.2) is extrapolated from the development pattern rather than modelled. The selected models look good partly because the two errors roughly cancel in the score.
- Fragile pairs. Some linear models on
[onehot]features (e.g.Lars) blow up after the \(\sinh\) back-transform, with near-singular fits giving astronomically large reserves. Clip or exclude them before averaging ranks.
For attribution, please cite this work as:
T. Moudiki (2026-10-05). Machine-learning loss reserving vs Mack Chain-Ladder under settlement speed-up and calendar inflation (Python version). Retrieved from https://thierrymoudiki.github.io/blog/2026/10/05/r/python/mlreserving-vs-mack-sweep-v2
BibTeX citation (remove empty spaces)
        @misc{ tmoudiki20261005,
          author = { T. Moudiki },
          title = { Machine-learning loss reserving vs Mack Chain-Ladder under settlement speed-up and calendar inflation (Python version) },
          url = { https://thierrymoudiki.github.io/blog/2026/10/05/r/python/mlreserving-vs-mack-sweep-v2 },
          year = { 2026 } }

Previous publications
- Machine-learning loss reserving vs Mack Chain-Ladder under settlement speed-up and calendar inflation (Python version) Oct 5, 2026
- mlreserve: machine-learning loss reserving on 'real-world' triangles (based on a 'ChainLadder' fork) Oct 3, 2026
- Analytics Pipeline for Dashboards, with Python, R and Javascript Sep 27, 2026
- Python version of Semi-parametric option pricing based on underlying's historical data (accepted at the osQF 2026 (ex R/Finance) conference) Sep 21, 2026
- Semi-parametric option pricing based on underlying's historical data (accepted at the osQF 2026 (ex R/Finance) conference) Sep 20, 2026
- Model-agnostic prediction intervals in Python and R: does nnetsauce's QuantileRegressor hold up? Sep 14, 2026
- ahead (Time Series Forecasting with uncertainty quantification) gets a lot faster to install: most dependencies are now optional Sep 8, 2026
- Skip the R/Python runtime: fast tabular dashboards with Observable Framework Aug 31, 2026
- PCARVFL vs CTGAN for synthetic tabular data generation on an insurance pricing dataset Aug 22, 2026
- 'Zero-Shot Probabilistic Stock Returns Forecasting with Pretrained RVFL Networks' accepted at COPA 2026 (and to appear in the Proceedings of Machine Learning Research) Aug 15, 2026
- 'PCARVFLSimulator': a GAN-like tabular data synthesizer built from PCA scores, a Random Vector Functional-Link network, and residuals bootstrapping Aug 10, 2026
- 'garchf': GARCH probabilistic forecasting with package 'forecast'-style interface (and 'rugarch' under the hood) Aug 1, 2026
- GPopt for R: Bayesian and conformal optimization of black-box functions and hyperparameter tuning Jul 26, 2026
- My last R posts: How conformalization helps weak models, fast conformal prediction with jackknife+ (and no refitting), and sklearn in R Jul 13, 2026
- Natively Interpretable Boosting Jul 12, 2026
- Fast conformal prediction (no refitting) for some Machine Learning models via closed-form jackknife plus Jun 27, 2026
- Using scikit-learn models in R easily with the tisthemachinelearner package Jun 21, 2026
- No-Code Machine Learning in Excel with the Techtonique API Jun 14, 2026
- How Conformal Prediction Makes Linear Models Good Enough — An Example Using R Package mlS3 Jun 7, 2026
- Techtonique dot net, the Machine Learning web API, is back online (but more like a passion project for now) May 31, 2026
- Conformalized TabICL: Prediction Intervals for a State-Of-The-Art Tabular Foundation Model in Python and R May 21, 2026
- Conformalized TabPFN: Prediction Intervals for a Pretrained Transformer for Tabular Data in Python and R May 17, 2026
- Probabilistic Time Series Cross-Validation with R package crossvalidation May 16, 2026
- One interface, (Almost) Every Classifier (and Regressor): unifiedml v0.3.0 May 9, 2026
- You Don't Need to Learn All the Weights on tabular data: The Case for rvflnet (a nonlinear expressive glmnet) on regression, classification and survival analysis May 2, 2026
- Survival analysis with sklearn, glmnet, keras, pytorch, lightgbm, xgboost, nnetsauce, mlsauce Part 2 Apr 28, 2026
- Any Sklearn Regressor as a Survival Model — Does It Actually Work? Benchmarking vs Established Packages Apr 26, 2026
- Conformal Optimization Beats Bayesian Optimization, Optuna and Random Search on 72 classification Datasets Apr 19, 2026
- `mlS3` — A Unified S3 Machine Learning Interface in R Apr 12, 2026
- One interface, (Almost) Every Classifier: unifiedml v0.2.1 Apr 4, 2026
- Techtonique dot net is down until further notice Apr 1, 2026
- Explaining Time-Series Forecasts with Sensitivity Analysis (ahead::dynrmf and external regressors) Mar 29, 2026
- Python version of 'Option pricing using time series models as market price of risk Pt.3' Mar 22, 2026
- Option pricing using time series models as market price of risk Pt.3 Mar 16, 2026
- Explaining Time-Series Forecasts with Exact Shapley Values (ahead::dynrmf with external regressors applied to scenarios) Mar 8, 2026
- My Presentation at Risk 2026: Lightweight Transfer Learning for Financial Forecasting Mar 1, 2026
- nnetsauce with and without jax for GPU acceleration Feb 23, 2026
- Understanding Boosted Configuration Networks (combined neural networks and boosting): An Intuitive Guide Through Their Hyperparameters Feb 16, 2026
- R version of Python package survivalist, for model-agnostic survival analysis Feb 9, 2026
- Presenting Lightweight Transfer Learning for Financial Forecasting (Risk 2026) Feb 4, 2026
- Option pricing using time series models as market price of risk Feb 1, 2026
- Enhancing Time Series Forecasting (ahead::ridge2f) with Attention-Based Context Vectors (ahead::contextridge2f) Jan 31, 2026
- Overfitting and scaling (on GPU T4) tests on nnetsauce.CustomRegressor Jan 29, 2026
- Beyond Cross-validation: Hyperparameter Optimization via Generalization Gap Modeling Jan 25, 2026
- GPopt for Machine Learning (hyperparameters' tuning) Jan 21, 2026
- rtopy: an R to Python bridge -- novelties Jan 8, 2026
- Python examples for 'Beyond Nelson-Siegel and splines: A model- agnostic Machine Learning framework for discount curve calibration, interpolation and extrapolation' Jan 3, 2026
- Forecasting benchmark: Dynrmf (a new serious competitor in town) vs Theta Method on M-Competitions and Tourism competitition Jan 1, 2026
- Finally figured out a way to port python packages to R using uv and reticulate: example with nnetsauce Dec 17, 2025
- Overfitting Random Fourier Features: Universal Approximation Property Dec 13, 2025
- Counterfactual Scenario Analysis with ahead::ridge2f Dec 11, 2025
- Zero-Shot Probabilistic Time Series Forecasting with TabPFN 2.5 and nnetsauce Dec 10, 2025
- ARIMA Pricing: Semi-Parametric Market price of risk for Risk-Neutral Pricing (code + preprint) Dec 7, 2025
- Analyzing Paper Reviews with LLMs: I Used ChatGPT, DeepSeek, Qwen, Mistral, Gemini, and Claude (and you should too + publish the analysis) Dec 3, 2025
- tisthemachinelearner: New Workflow with uv for R Integration of scikit-learn Dec 1, 2025
- (ICYMI) RPweave: Unified R + Python + LaTeX System using uv Nov 21, 2025
- unifiedml: A Unified Machine Learning Interface for R, is now on CRAN + Discussion about AI replacing humans Nov 16, 2025
- Context-aware Theta forecasting Method: Extending Classical Time Series Forecasting with Machine Learning Nov 13, 2025
- unifiedml in R: A Unified Machine Learning Interface Nov 5, 2025
- Deterministic Shift Adjustment in Arbitrage-Free Pricing (historical to risk-neutral short rates) Oct 28, 2025
- New instantaneous short rates models with their deterministic shift adjustment, for historical and risk-neutral simulation Oct 27, 2025
- RPweave: Unified R + Python + LaTeX System using uv Oct 19, 2025
- GAN-like Synthetic Data Generation Examples (on univariate, multivariate distributions, digits recognition, Fashion-MNIST, stock returns, and Olivetti faces) with DistroSimulator Oct 19, 2025
- R port of llama2.c Oct 9, 2025
- Native uncertainty quantification for time series with NGBoost Oct 8, 2025
- NGBoost (Natural Gradient Boosting) for Regression, Classification, Time Series forecasting and Reserving Oct 6, 2025
- Real-time pricing with a pretrained probabilistic stock return model Oct 1, 2025
- Combining any model with GARCH(1,1) for probabilistic stock forecasting Sep 23, 2025
- Generating Synthetic Data with R-vine Copulas using esgtoolkit in R Sep 21, 2025
- Reimagining Equity Solvency Capital Requirement Approximation (one of my Master's Thesis subjects): From Bilinear Interpolation to Probabilistic Machine Learning Sep 16, 2025
- Transfer Learning using ahead::ridge2f on synthetic stocks returns Pt.2: synthetic data generation Sep 9, 2025
- Transfer Learning using ahead::ridge2f on synthetic stocks returns Sep 8, 2025
- I'm supposed to present 'Conformal Predictive Simulations for Univariate Time Series' at COPA CONFERENCE 2025 in London... Sep 4, 2025
- external regressors in ahead::dynrmf's interface for Machine learning forecasting Sep 1, 2025
- Another interesting decision, now for 'Beyond Nelson-Siegel and splines: A model-agnostic Machine Learning framework for discount curve calibration, interpolation and extrapolation' Aug 20, 2025
- Boosting any randomized based learner for regression, classification and univariate/multivariate time series forcasting Jul 26, 2025
- New nnetsauce version with CustomBackPropRegressor (CustomRegressor with Backpropagation) and ElasticNet2Regressor (Ridge2 with ElasticNet regularization) Jul 15, 2025
- mlsauce (home to a model-agnostic gradient boosting algorithm) can now be installed from PyPI. Jul 10, 2025
- A user-friendly graphical interface to techtonique dot net's API (will eventually contain graphics). Jul 8, 2025
- Calling =TECHTO_MLCLASSIFICATION for Machine Learning supervised CLASSIFICATION in Excel is just a matter of copying and pasting Jul 7, 2025
- Calling =TECHTO_MLREGRESSION for Machine Learning supervised regression in Excel is just a matter of copying and pasting Jul 6, 2025
- Calling =TECHTO_RESERVING and =TECHTO_MLRESERVING for claims triangle reserving in Excel is just a matter of copying and pasting Jul 5, 2025
- Calling =TECHTO_SURVIVAL for Survival Analysis in Excel is just a matter of copying and pasting Jul 4, 2025
- Calling =TECHTO_SIMULATION for Stochastic Simulation in Excel is just a matter of copying and pasting Jul 3, 2025
- Calling =TECHTO_FORECAST for forecasting in Excel is just a matter of copying and pasting Jul 2, 2025
- Random Vector Functional Link (RVFL) artificial neural network with 2 regularization parameters successfully used for forecasting/synthetic simulation in professional settings: Extensions (including Bayesian) Jul 1, 2025
- R version of 'Backpropagating quasi-randomized neural networks' Jun 24, 2025
- Backpropagating quasi-randomized neural networks Jun 23, 2025
- Beyond ARMA-GARCH: leveraging any statistical model for volatility forecasting Jun 21, 2025
- Stacked generalization (Machine Learning model stacking) + conformal prediction for forecasting with ahead::mlf Jun 18, 2025
- An Overfitting dilemma: XGBoost Default Hyperparameters vs GenericBooster + LinearRegression Default Hyperparameters Jun 14, 2025
- Programming language-agnostic reserving using RidgeCV, LightGBM, XGBoost, and ExtraTrees Machine Learning models Jun 13, 2025
- Free R, Python and SQL editors in techtonique dot net Jun 9, 2025
- Beyond Nelson-Siegel and splines: A model-agnostic Machine Learning framework for discount curve calibration, interpolation and extrapolation Jun 7, 2025
- scikit-learn, glmnet, xgboost, lightgbm, pytorch, keras, nnetsauce in probabilistic Machine Learning (for longitudinal data) Reserving (work in progress) Jun 6, 2025
- R version of Probabilistic Machine Learning (for longitudinal data) Reserving (work in progress) Jun 5, 2025
- Probabilistic Machine Learning (for longitudinal data) Reserving (work in progress) Jun 4, 2025
- Python version of Beyond ARMA-GARCH: leveraging model-agnostic Quasi-Randomized networks and conformal prediction for nonparametric probabilistic stock forecasting (ML-ARCH) Jun 3, 2025
- Beyond ARMA-GARCH: leveraging model-agnostic Machine Learning and conformal prediction for nonparametric probabilistic stock forecasting (ML-ARCH) Jun 2, 2025
- Permutations and SHAPley values for feature importance in techtonique dot net's API (with R + Python + the command line) Jun 1, 2025
- Which patient is going to survive longer? Another guide to using techtonique dot net's API (with R + Python + the command line) for survival analysis May 31, 2025
- A Guide to Using techtonique.net's API and rush for simulating and plotting Stochastic Scenarios May 30, 2025
- Simulating Stochastic Scenarios with Diffusion Models: A Guide to Using techtonique.net's API for the purpose May 29, 2025
- Will my apartment in 5th avenue be overpriced or not? Harnessing the power of www.techtonique.net (+ xgboost, lightgbm, catboost) to find out May 28, 2025
- How long must I wait until something happens: A Comprehensive Guide to Survival Analysis via an API May 27, 2025
- Harnessing the Power of techtonique.net: A Comprehensive Guide to Machine Learning Classification via an API May 26, 2025
- Quantile regression with any regressor -- Examples with RandomForestRegressor, RidgeCV, KNeighborsRegressor May 20, 2025
- Survival stacking: survival analysis translated as supervised classification in R and Python May 5, 2025
- 'Bayesian' optimization of hyperparameters in a R machine learning model using the bayesianrvfl package Apr 25, 2025
- A lightweight interface to scikit-learn in R: Bayesian and Conformal prediction Apr 21, 2025
- A lightweight interface to scikit-learn in R Pt.2: probabilistic time series forecasting in conjunction with ahead::dynrmf Apr 20, 2025
- Extending the Theta forecasting method to GLMs, GAMs, GLMBOOST and attention: benchmarking on Tourism, M1, M3 and M4 competition data sets (28000 series) Apr 14, 2025
- Extending the Theta forecasting method to GLMs and attention Apr 8, 2025
- Nonlinear conformalized Generalized Linear Models (GLMs) with R package 'rvfl' (and other models) Mar 31, 2025
- Probabilistic Time Series Forecasting (predictive simulations) in Microsoft Excel using Python, xlwings lite and www.techtonique.net Mar 28, 2025
- Conformalize (improved prediction intervals and simulations) any R Machine Learning model with misc::conformalize Mar 25, 2025
- My poster for the 18th FINANCIAL RISKS INTERNATIONAL FORUM by Institut Louis Bachelier/Fondation du Risque/Europlace Institute of Finance Mar 19, 2025
- Interpretable probabilistic kernel ridge regression using Matérn 3/2 kernels Mar 16, 2025
- (News from) Probabilistic Forecasting of univariate and multivariate Time Series using Quasi-Randomized Neural Networks (Ridge2) and Conformal Prediction Mar 9, 2025
- Word-Online: re-creating Karpathy's char-RNN (with supervised linear online learning of word embeddings) for text completion Mar 8, 2025
- CRAN-like repository for most recent releases of Techtonique's R packages Mar 2, 2025
- Presenting 'Online Probabilistic Estimation of Carbon Beta and Carbon Shapley Values for Financial and Climate Risk' at Institut Louis Bachelier Feb 27, 2025
- Web app with DeepSeek R1 and Hugging Face API for chatting Feb 23, 2025
- tisthemachinelearner: A Lightweight interface to scikit-learn with 2 classes, Classifier and Regressor (in Python and R) Feb 17, 2025
- R version of survivalist: Probabilistic model-agnostic survival analysis using scikit-learn, xgboost, lightgbm (and conformal prediction) Feb 12, 2025
- Model-agnostic global Survival Prediction of Patients with Myeloid Leukemia in QRT/Gustave Roussy Challenge (challengedata.ens.fr): Python's survivalist Quickstart Feb 10, 2025
- A simple test of the martingale hypothesis in esgtoolkit Feb 3, 2025
- Command Line Interface (CLI) for techtonique.net's API Jan 31, 2025
- Gradient-Boosting and Boostrap aggregating anything (alert: high performance): Part5, easier install and Rust backend Jan 27, 2025
- Just got a paper on conformal prediction REJECTED by International Journal of Forecasting despite evidence on 30,000 time series (and more). What's going on? Part2: 1311 time series from the Tourism competition Jan 20, 2025
- Techtonique is released! (with a tutorial in various programming languages and formats) Jan 14, 2025
- Univariate and Multivariate Probabilistic Forecasting with nnetsauce and TabPFN Jan 14, 2025
- Just got a paper on conformal prediction REJECTED by International Journal of Forecasting despite evidence on 30,000 time series (and more). What's going on? Jan 5, 2025
- Python and Interactive dashboard version of Stock price forecasting with Deep Learning: throwing power at the problem (and why it won't make you rich) Dec 31, 2024
- Stock price forecasting with Deep Learning: throwing power at the problem (and why it won't make you rich) Dec 29, 2024
- No-code Machine Learning Cross-validation and Interpretability in techtonique.net Dec 23, 2024
- survivalist: Probabilistic model-agnostic survival analysis using scikit-learn, glmnet, xgboost, lightgbm, pytorch, keras, nnetsauce and mlsauce Dec 15, 2024
- Model-agnostic 'Bayesian' optimization (for hyperparameter tuning) using conformalized surrogates in GPopt Dec 9, 2024
- You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTS Pt.2: Generic Gradient Boosting Dec 1, 2024
- You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTS Nov 24, 2024
- Unified interface and conformal prediction (calibrated prediction intervals) for R package forecast (and 'affiliates') Nov 23, 2024
- GLMNet in Python: Generalized Linear Models Nov 18, 2024
- Gradient-Boosting anything (alert: high performance): Part4, Time series forecasting Nov 10, 2024
- Predictive scenarios simulation in R, Python and Excel using Techtonique API Nov 3, 2024
- Chat with your tabular data in www.techtonique.net Oct 30, 2024
- Gradient-Boosting anything (alert: high performance): Part3, Histogram-based boosting Oct 28, 2024
- R editor and SQL console (in addition to Python editors) in www.techtonique.net Oct 21, 2024
- R and Python consoles + JupyterLite in www.techtonique.net Oct 15, 2024
- Gradient-Boosting anything (alert: high performance): Part2, R version Oct 14, 2024
- Gradient-Boosting anything (alert: high performance) Oct 6, 2024
- Benchmarking 30 statistical/Machine Learning models on the VN1 Forecasting -- Accuracy challenge Oct 4, 2024
- Automated random variable distribution inference using Kullback-Leibler divergence and simulating best-fitting distribution Oct 2, 2024
- Forecasting in Excel using Techtonique's Machine Learning APIs under the hood Sep 30, 2024
- Techtonique web app for data-driven decisions using Mathematics, Statistics, Machine Learning, and Data Visualization Sep 25, 2024
- Parallel for loops (Map or Reduce) + New versions of nnetsauce and ahead Sep 16, 2024
- Adaptive (online/streaming) learning with uncertainty quantification using Polyak averaging in learningmachine Sep 10, 2024
- New versions of nnetsauce and ahead Sep 9, 2024
- Prediction sets and prediction intervals for conformalized Auto XGBoost, Auto LightGBM, Auto CatBoost, Auto GradientBoosting Sep 2, 2024
- Quick/automated R package development workflow (assuming you're using macOS or Linux) Part2 Aug 30, 2024
- R package development workflow (assuming you're using macOS or Linux) Aug 27, 2024
- A new method for deriving a nonparametric confidence interval for the mean Aug 26, 2024
- Conformalized adaptive (online/streaming) learning using learningmachine in Python and R Aug 19, 2024
- Bayesian (nonlinear) adaptive learning Aug 12, 2024
- Auto XGBoost, Auto LightGBM, Auto CatBoost, Auto GradientBoosting Aug 5, 2024
- Copulas for uncertainty quantification in time series forecasting Jul 28, 2024
- Forecasting uncertainty: sequential split conformal prediction + Block bootstrap (web app) Jul 22, 2024
- learningmachine for Python (new version) Jul 15, 2024
- learningmachine v2.0.0: Machine Learning with explanations and uncertainty quantification Jul 8, 2024
- My presentation at ISF 2024 conference (slides with nnetsauce probabilistic forecasting news) Jul 3, 2024
- 10 uncertainty quantification methods in nnetsauce forecasting Jul 1, 2024
- Forecasting with XGBoost embedded in Quasi-Randomized Neural Networks Jun 24, 2024
- Forecasting Monthly Airline Passenger Numbers with Quasi-Randomized Neural Networks Jun 17, 2024
- Automated hyperparameter tuning using any conformalized surrogate Jun 9, 2024
- Recognizing handwritten digits with Ridge2Classifier Jun 3, 2024
- Forecasting the Economy May 27, 2024
- A detailed introduction to Deep Quasi-Randomized 'neural' networks May 19, 2024
- Probability of receiving a loan; using learningmachine May 12, 2024
- mlsauce's `v0.18.2`: various examples and benchmarks with dimension reduction May 6, 2024
- mlsauce's `v0.17.0`: boosting with Elastic Net, polynomials and heterogeneity in explanatory variables Apr 29, 2024
- mlsauce's `v0.13.0`: taking into account inputs heterogeneity through clustering Apr 21, 2024
- mlsauce's `v0.12.0`: prediction intervals for LSBoostRegressor Apr 15, 2024
- Conformalized predictive simulations for univariate time series on more than 250 data sets Apr 7, 2024
- learningmachine v1.1.2: for Python Apr 1, 2024
- learningmachine v1.0.0: prediction intervals around the probability of the event 'a tumor being malignant' Mar 25, 2024
- Bayesian inference and conformal prediction (prediction intervals) in nnetsauce v0.18.1 Mar 18, 2024
- Multiple examples of Machine Learning forecasting with ahead Mar 11, 2024
- rtopy (v0.1.1): calling R functions in Python Mar 4, 2024
- ahead forecasting (v0.10.0): fast time series model calibration and Python plots Feb 26, 2024
- A plethora of datasets at your fingertips Part3: how many times do couples cheat on each other? Feb 19, 2024
- nnetsauce's introduction as of 2024-02-11 (new version 0.17.0) Feb 11, 2024
- Tuning Machine Learning models with GPopt's new version Part 2 Feb 5, 2024
- Tuning Machine Learning models with GPopt's new version Jan 29, 2024
- Subsampling continuous and discrete response variables Jan 22, 2024
- DeepMTS, a Deep Learning Model for Multivariate Time Series Jan 15, 2024
- A classifier that's very accurate (and deep) Pt.2: there are > 90 classifiers in nnetsauce Jan 8, 2024
- learningmachine: prediction intervals for conformalized Kernel ridge regression and Random Forest Jan 1, 2024
- A plethora of datasets at your fingertips Part2: how many times do couples cheat on each other? Descriptive analytics, interpretability and prediction intervals using conformal prediction Dec 25, 2023
- Diffusion models in Python with esgtoolkit (Part2) Dec 18, 2023
- Diffusion models in Python with esgtoolkit Dec 11, 2023
- Julia packaging at the command line Dec 4, 2023
- Quasi-randomized nnetworks in Julia, Python and R Nov 27, 2023
- A plethora of datasets at your fingertips Nov 20, 2023
- A classifier that's very accurate (and deep) Nov 12, 2023
- mlsauce version 0.8.10: Statistical/Machine Learning with Python and R Nov 5, 2023
- AutoML in nnetsauce (randomized and quasi-randomized nnetworks) Pt.2: multivariate time series forecasting Oct 29, 2023
- AutoML in nnetsauce (randomized and quasi-randomized nnetworks) Oct 22, 2023
- Version v0.14.0 of nnetsauce for R and Python Oct 16, 2023
- A diffusion model: G2++ Oct 9, 2023
- Diffusion models in ESGtoolkit + announcements Oct 2, 2023
- An infinity of time series forecasting models in nnetsauce (Part 2 with uncertainty quantification) Sep 25, 2023
- (News from) forecasting in Python with ahead (progress bars and plots) Sep 18, 2023
- Forecasting in Python with ahead Sep 11, 2023
- Risk-neutralize simulations Sep 4, 2023
- Comparing cross-validation results using crossval_ml and boxplots Aug 27, 2023
- Reminder Apr 30, 2023
- Did you ask ChatGPT about who you are? Apr 16, 2023
- A new version of nnetsauce (randomized and quasi-randomized 'neural' networks) Apr 2, 2023
- Simple interfaces to the forecasting API Nov 23, 2022
- A web application for forecasting in Python, R, Ruby, C#, JavaScript, PHP, Go, Rust, Java, MATLAB, etc. Nov 2, 2022
- Prediction intervals (not only) for Boosted Configuration Networks in Python Oct 5, 2022
- Boosted Configuration (neural) Networks Pt. 2 Sep 3, 2022
- Boosted Configuration (_neural_) Networks for classification Jul 21, 2022
- A Machine Learning workflow using Techtonique Jun 6, 2022
- Super Mario Bros © in the browser using PyScript May 8, 2022
- News from ESGtoolkit, ycinterextra, and nnetsauce Apr 4, 2022
- Explaining a Keras _neural_ network predictions with the-teller Mar 11, 2022
- New version of nnetsauce -- various quasi-randomized networks Feb 12, 2022
- A dashboard illustrating bivariate time series forecasting with `ahead` Jan 14, 2022
- Hundreds of Statistical/Machine Learning models for univariate time series, using ahead, ranger, xgboost, and caret Dec 20, 2021
- Forecasting with `ahead` (Python version) Dec 13, 2021
- Tuning and interpreting LSBoost Nov 15, 2021
- Time series cross-validation using `crossvalidation` (Part 2) Nov 7, 2021
- Fast and scalable forecasting with ahead::ridge2f Oct 31, 2021
- Automatic Forecasting with `ahead::dynrmf` and Ridge regression Oct 22, 2021
- Forecasting with `ahead` Oct 15, 2021
- Classification using linear regression Sep 26, 2021
- `crossvalidation` and random search for calibrating support vector machines Aug 6, 2021
- parallel grid search cross-validation using `crossvalidation` Jul 31, 2021
- `crossvalidation` on R-universe, plus a classification example Jul 23, 2021
- Documentation and source code for GPopt, a package for Bayesian optimization Jul 2, 2021
- Hyperparameters tuning with GPopt Jun 11, 2021
- A forecasting tool (API) with examples in curl, R, Python May 28, 2021
- Bayesian Optimization with GPopt Part 2 (save and resume) Apr 30, 2021
- Bayesian Optimization with GPopt Apr 16, 2021
- Compatibility of nnetsauce and mlsauce with scikit-learn Mar 26, 2021
- Explaining xgboost predictions with the teller Mar 12, 2021
- An infinity of time series models in nnetsauce Mar 6, 2021
- New activation functions in mlsauce's LSBoost Feb 12, 2021
- 2020 recap, Gradient Boosting, Generalized Linear Models, AdaOpt with nnetsauce and mlsauce Dec 29, 2020
- A deeper learning architecture in nnetsauce Dec 18, 2020
- Classify penguins with nnetsauce's MultitaskClassifier Dec 11, 2020
- Bayesian forecasting for uni/multivariate time series Dec 4, 2020
- Generalized nonlinear models in nnetsauce Nov 28, 2020
- Boosting nonlinear penalized least squares Nov 21, 2020
- Statistical/Machine Learning explainability using Kernel Ridge Regression surrogates Nov 6, 2020
- NEWS Oct 30, 2020
- A glimpse into my PhD journey Oct 23, 2020
- Submitting R package to CRAN Oct 16, 2020
- Simulation of dependent variables in ESGtoolkit Oct 9, 2020
- Forecasting lung disease progression Oct 2, 2020
- New nnetsauce Sep 25, 2020
- Technical documentation Sep 18, 2020
- A new version of nnetsauce, and a new Techtonique website Sep 11, 2020
- Back next week, and a few announcements Sep 4, 2020
- Explainable 'AI' using Gradient Boosted randomized networks Pt2 (the Lasso) Jul 31, 2020
- LSBoost: Explainable 'AI' using Gradient Boosted randomized networks (with examples in R and Python) Jul 24, 2020
- nnetsauce version 0.5.0, randomized neural networks on GPU Jul 17, 2020
- Maximizing your tip as a waiter (Part 2) Jul 10, 2020
- New version of mlsauce, with Gradient Boosted randomized networks and stump decision trees Jul 3, 2020
- Announcements Jun 26, 2020
- Parallel AdaOpt classification Jun 19, 2020
- Comments section and other news Jun 12, 2020
- Maximizing your tip as a waiter Jun 5, 2020
- AdaOpt classification on MNIST handwritten digits (without preprocessing) May 29, 2020
- AdaOpt (a probabilistic classifier based on a mix of multivariable optimization and nearest neighbors) for R May 22, 2020
- AdaOpt May 15, 2020
- Custom errors for cross-validation using crossval::crossval_ml May 8, 2020
- Documentation+Pypi for the `teller`, a model-agnostic tool for Machine Learning explainability May 1, 2020
- Encoding your categorical variables based on the response variable and correlations Apr 24, 2020
- Linear model, xgboost and randomForest cross-validation using crossval::crossval_ml Apr 17, 2020
- Grid search cross-validation using crossval Apr 10, 2020
- Documentation for the querier, a query language for Data Frames Apr 3, 2020
- Time series cross-validation using crossval Mar 27, 2020
- On model specification, identification, degrees of freedom and regularization Mar 20, 2020
- Import data into the querier (now on Pypi), a query language for Data Frames Mar 13, 2020
- R notebooks for nnetsauce Mar 6, 2020
- Version 0.4.0 of nnetsauce, with fruits and breast cancer classification Feb 28, 2020
- Create a specific feed in your Jekyll blog Feb 21, 2020
- Git/Github for contributing to package development Feb 14, 2020
- Feedback forms for contributing Feb 7, 2020
- nnetsauce for R Jan 31, 2020
- A new version of nnetsauce (v0.3.1) Jan 24, 2020
- ESGtoolkit, a tool for Monte Carlo simulation (v0.2.0) Jan 17, 2020
- Search bar, new year 2020 Jan 10, 2020
- 2019 Recap, the nnetsauce, the teller and the querier Dec 20, 2019
- Understanding model interactions with the `teller` Dec 13, 2019
- Using the `teller` on a classifier Dec 6, 2019
- Benchmarking the querier's verbs Nov 29, 2019
- Composing the querier's verbs for data wrangling Nov 22, 2019
- Comparing and explaining model predictions with the teller Nov 15, 2019
- Tests for the significance of marginal effects in the teller Nov 8, 2019
- Introducing the teller Nov 1, 2019
- Introducing the querier Oct 25, 2019
- Prediction intervals for nnetsauce models Oct 18, 2019
- Using R in Python for statistical learning/data science Oct 11, 2019
- Model calibration with `crossval` Oct 4, 2019
- Bagging in the nnetsauce Sep 25, 2019
- Adaboost learning with nnetsauce Sep 18, 2019
- Change in blog's presentation Sep 4, 2019
- nnetsauce on Pypi Jun 5, 2019
- More nnetsauce (examples of use) May 9, 2019
- nnetsauce Mar 13, 2019
- crossval Mar 13, 2019
- test Mar 10, 2019
Comments powered by Talkyard.