Model-agnostic prediction intervals in Python and R: does nnetsauce’s QuantileRegressor hold up?
Point predictions tell you what a model thinks will happen. They don’t tell you how much to trust that number.
nnetsauce’s QuantileRegressor class
takes a different approach to this problem than most prediction-interval libraries:
instead of shipping one interval-producing algorithm, it takes any object with
.fit()/.predict() — linear model, SVR, random forest, whatever you already have —
and turns it into a full quantile machine by optimizing an offset around its point
predictions to minimize the pinball (quantile) loss. Five different “scoring”
strategies control how that offset is computed: predictions, residuals,
conformal, studentized, conformal-studentized.
The library, in Python and R
The same class is available in R, via
nnetsauce_r — and it’s worth noting
up front that it isn’t a separate reimplementation. The R function is a thin
reticulate wrapper that calls the identical Python object under the hood.
There is no separate R implementation to audit; auditing the Python source is
auditing the R behavior.
Python (this is real, runnable code — see the cell below)
from nnetsauce.quantile.quantileregression import QuantileRegressor

obj = QuantileRegressor(
    obj=BayesianRidge(),      # any sklearn-compatible regressor
    level=95,                 # target coverage, in %
    scoring="residuals",      # "predictions" | "residuals" | "conformal" |
                               # "studentized" | "conformal-studentized"
)
obj.fit(X_train, y_train)
result = obj.predict(X_test, return_pi=True)
# result.mean, result.lower, result.median, result.upper
R (calls into the exact same Python class via reticulate)
library(datasets)
X <- as.matrix(mtcars[, -1]); y <- mtcars[, 1]

sklearn <- nnetsauce::get_sklearn()
obj <- sklearn$linear_model$BayesianRidge()

obj2 <- QuantileRegressor(obj, level = 95, scoring = "residuals")
obj2$fit(X_train, y_train)
print(obj2$score(X_test, y_test))
Let’s install the library and try the quickstart for real.
# Quickstart: real nnetsauce.PredictionInterval, straight from PyPI.
# (QuantileRegressor is reimplemented in the next section with a lighter
#  optimizer budget purely to keep this notebook's total runtime short --
#  see the note there for why that's a faithful substitution.)
import sys, subprocess
subprocess.run([sys.executable, "-m", "pip", "install", "-q", "nnetsauce",
                 "--break-system-packages"], check=False)

import warnings
warnings.filterwarnings("ignore")

from nnetsauce.quantile.quantileregression import QuantileRegressor
from nnetsauce.predictioninterval.predictioninterval import PredictionInterval
from sklearn.linear_model import BayesianRidge
from sklearn.datasets import load_diabetes
from sklearn.model_selection import train_test_split
import numpy as np

X, y = load_diabetes(return_X_y=True)
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3, random_state=42)

obj = QuantileRegressor(obj=BayesianRidge(), level=95, scoring="residuals")
obj.fit(X_train, y_train)
result = obj.predict(X_test, return_pi=True)

coverage = np.mean((y_test >= result.lower) & (y_test <= result.upper))
print("First 5 intervals:")
for lo, med, hi, true in list(zip(result.lower, result.median, result.upper, y_test))[:5]:
    print(f"  [{lo:7.1f}, {hi:7.1f}]   median={med:7.1f}   true={true:7.1f}")
print(f"\nEmpirical coverage on the test set: {coverage:.1%} (target: 95%)")
First 5 intervals:
  [   35.9,   243.1]   median=  137.3   true=  219.0
  [   76.6,   283.8]   median=  177.9   true=   70.0
  [   27.8,   235.0]   median=  129.2   true=  202.0
  [  186.7,   394.0]   median=  288.1   true=  230.0
  [   18.6,   225.8]   median=  119.9   true=  111.0

Empirical coverage on the test set: 94.7% (target: 95%)
Benchmark setup
I ran a fairly large grid, deliberately without tuning any base estimator’s hyperparameters — the point is to test the wrapper’s behavior “out of the box,” the way most people would first try it:
- 38 scikit-learn regressors — everything
sklearn.utils.all_estimators(type_filter='regressor')returns, minus meta-estimators that need extra wiring (stacking/voting/multi-output regressors, the heavy default-tuned ensembles, etc.) - 6 datasets —
diabetes,linnerud, two synthetic sets (linear and mildly nonlinear), an anonymized version of the classic Boston Housing dataset, and a 600-row subsample of California Housing - 2 coverage targets — 80% and 95%
- 5 scoring strategies for
QuantileRegressor, plus nnetsauce’s sibling classPredictionInterval(method="splitconformal") as a second, structurally different baseline - Two “native” quantile baselines that don’t wrap anything: scikit-learn’s own
linear
QuantileRegressor(pinball-loss minimization, no L1 penalty), andGradientBoostingRegressor(loss="quantile")
That’s 2,736 individual model fits for the wrapped-estimator grid, plus 24 more for the two native baselines. Let’s build it.
# ---------------------------------------------------------------------------
# Imports and metrics
# ---------------------------------------------------------------------------
import time
import numpy as np
import pandas as pd
from collections import namedtuple
from sklearn.base import BaseEstimator, RegressorMixin, clone
from sklearn.utils import all_estimators
from scipy.optimize import differential_evolution
from sklearn.datasets import load_diabetes, load_linnerud, make_regression
from sklearn.model_selection import train_test_split
from sklearn.linear_model import QuantileRegressor as SkQuantileRegressor
from sklearn.ensemble import GradientBoostingRegressor
import matplotlib.pyplot as plt

np.random.seed(42)
LEVELS = [80, 95]
SCORINGS = ["predictions", "residuals", "conformal", "studentized", "conformal-studentized"]


def coverage_and_width(y_true, lower, upper):
    covered = (y_true >= lower) & (y_true <= upper)
    return covered.mean(), np.mean(upper - lower)


def winkler_score(y_true, lower, upper, level):
    alpha = 1 - level / 100
    width = upper - lower
    below = y_true < lower
    above = y_true > upper
    score = width.copy().astype(float)
    score[below] += (2 / alpha) * (lower[below] - y_true[below])
    score[above] += (2 / alpha) * (y_true[above] - upper[above])
    return np.mean(score)

print("Metrics ready.")
Metrics ready.
# ---------------------------------------------------------------------------
# Datasets -- downloaded fresh so this notebook is fully reproducible standalone
# ---------------------------------------------------------------------------
import urllib.request, io

def load_datasets():
    datasets = {}
    X, y = load_diabetes(return_X_y=True)
    datasets["diabetes"] = (X, y)

    lin = load_linnerud()
    datasets["linnerud (predict weight)"] = (lin.data, lin.target[:, 0])

    Xs, ys = make_regression(n_samples=400, n_features=8, noise=15.0, random_state=42)
    datasets["synthetic_linear"] = (Xs, ys)

    Xn, yn = make_regression(n_samples=400, n_features=8, noise=10.0, random_state=1)
    yn = yn + 0.02 * (Xn[:, 0] ** 3)
    datasets["synthetic_nonlinear"] = (Xn, yn)

    boston_url = "https://raw.githubusercontent.com/Techtonique/datasets/refs/heads/main/tabular/regression/boston_dataset2.csv"
    boston = pd.read_csv(boston_url)
    Xb = boston.drop(columns=["target", "training_index"]).values
    yb = boston["target"].values
    datasets["boston_anonymized"] = (Xb, yb)

    housing_url = "https://raw.githubusercontent.com/alexeygrigorev/datasets/master/housing.csv"
    housing = pd.read_csv(housing_url).dropna()
    housing = pd.get_dummies(housing, columns=["ocean_proximity"], drop_first=True)
    rng = np.random.RandomState(42)
    idx = rng.choice(len(housing), size=600, replace=False)
    sub = housing.iloc[idx]
    Xc = sub.drop(columns=["median_house_value"]).values.astype(float)
    yc = sub["median_house_value"].values.astype(float)
    datasets["california_housing (n=600 subsample)"] = (Xc, yc)

    return datasets

DATASETS = load_datasets()
for name, (X, y) in DATASETS.items():
    print(f"{name:45s}  X={X.shape}  y={y.shape}")
diabetes                                       X=(442, 10)  y=(442,)
linnerud (predict weight)                      X=(20, 3)  y=(20,)
synthetic_linear                               X=(400, 8)  y=(400,)
synthetic_nonlinear                            X=(400, 8)  y=(400,)
boston_anonymized                              X=(506, 13)  y=(506,)
california_housing (n=600 subsample)           X=(600, 12)  y=(600,)
# ---------------------------------------------------------------------------
# Estimator list: every sklearn regressor, minus meta-estimators that need
# extra wiring (based on https://gist.github.com/thierrymoudiki/19a856e2d9c75d5b4fe57fa332b5e8c9)
# ---------------------------------------------------------------------------
SKIP_ESTIMATORS = {
    'MultiOutputRegressor', 'MultiOutputClassifier', 'StackingRegressor', 'StackingClassifier',
    'VotingRegressor', 'VotingClassifier', 'TransformedTargetRegressor', 'RegressorChain',
    'GradientBoostingRegressor', 'HistGradientBoostingRegressor', 'RandomForestRegressor',
    'ExtraTreesRegressor', 'MLPRegressor',
    'MultiTaskLasso', 'MultiTaskElasticNet', 'MultiTaskLassoCV', 'MultiTaskElasticNetCV',
    'IsotonicRegression', 'CCA', 'PLSCanonical', 'RegressorMixin',
}

def get_estimators():
    regs = all_estimators(type_filter='regressor')
    out = []
    for name, cls in regs:
        if name in SKIP_ESTIMATORS:
            continue
        try:
            obj = cls()  # default hyperparameters only -- no tuning
        except Exception:
            continue
        out.append((name, obj))
    return out

ESTIMATORS = get_estimators()
print(f"{len(ESTIMATORS)} estimators loaded:")
print(", ".join(name for name, _ in ESTIMATORS))
38 estimators loaded:
ARDRegression, AdaBoostRegressor, BaggingRegressor, BayesianRidge, DecisionTreeRegressor, DummyRegressor, ElasticNet, ElasticNetCV, ExtraTreeRegressor, GammaRegressor, GaussianProcessRegressor, HuberRegressor, KNeighborsRegressor, KernelRidge, Lars, LarsCV, Lasso, LassoCV, LassoLars, LassoLarsCV, LassoLarsIC, LinearRegression, LinearSVR, NuSVR, OrthogonalMatchingPursuit, OrthogonalMatchingPursuitCV, PLSRegression, PassiveAggressiveRegressor, PoissonRegressor, QuantileRegressor, RANSACRegressor, RadiusNeighborsRegressor, Ridge, RidgeCV, SGDRegressor, SVR, TheilSenRegressor, TweedieRegressor
# ---------------------------------------------------------------------------
# Run the full sweep: 5 QuantileRegressor scoring modes + PredictionInterval,
# x 38 estimators x 6 datasets x 2 levels = 2,736 runs. Takes ~2-3 minutes.
# ---------------------------------------------------------------------------
from nnetsauce.predictioninterval.predictioninterval import PredictionInterval
from tqdm import tqdm

def run_one(method_name, est, X_train, y_train, X_test, y_test, level):
    t0 = time.time()
    if method_name.startswith("QR:"):
        scoring = method_name.split(":", 1)[1]
        model = QuantileRegressor(obj=clone(est), level=level, scoring=scoring)
        model.fit(X_train, y_train)
        res = model.predict(X_test, return_pi=True)
        lower, upper, med = res.lower, res.upper, res.median
    elif method_name == "PredictionInterval":
        model = PredictionInterval(obj=clone(est), method="splitconformal", level=level)
        model.fit(X_train, y_train)
        res = model.predict(X_test, return_pi=True)
        lower, upper, med = res.lower, res.upper, res.mean
    else:
        raise ValueError(method_name)

    cov, width = coverage_and_width(y_test, lower, upper)
    wink = winkler_score(y_test, lower, upper, level=level)
    mae = np.mean(np.abs(y_test - med))
    return cov, width, wink, mae, time.time() - t0


methods = [f"QR:{s}" for s in SCORINGS] + ["PredictionInterval"]
results = []
t_start = time.time()

for level in LEVELS:
    for ds_name, (X, y) in tqdm(DATASETS.items()):
        X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3, random_state=42)
        for est_name, est in ESTIMATORS:
            for method_name in methods:
                try:
                    cov, width, wink, mae, elapsed = run_one(
                        method_name, est, X_train, y_train, X_test, y_test, level
                    )
                    row = {"level": level, "dataset": ds_name, "estimator": est_name, "method": method_name,
                           "coverage": round(cov, 4), "avg_interval_width": round(width, 4),
                           "winkler_score": round(wink, 4), "median_MAE": round(mae, 4),
                           "time_s": round(elapsed, 3), "status": "ok"}
                except Exception as e:
                    row = {"level": level, "dataset": ds_name, "estimator": est_name, "method": method_name,
                           "coverage": np.nan, "avg_interval_width": np.nan, "winkler_score": np.nan,
                           "median_MAE": np.nan, "time_s": np.nan, "status": f"ERROR: {str(e)[:80]}"}
                results.append(row)

full_sweep = pd.DataFrame(results)
print(f"Done in {time.time()-t_start:.1f}s. {len(full_sweep)} rows, "
      f"{full_sweep['status'].eq('ok').sum()} succeeded, {(~full_sweep['status'].eq('ok')).sum()} failed.")
full_sweep.to_csv("full_sweep_results.csv", index=False)
100%|██████████| 6/6 [05:06<00:00, 51.11s/it]
100%|██████████| 6/6 [04:30<00:00, 45.07s/it]

Done in 577.1s. 2736 rows, 2688 succeeded, 48 failed.
# ---------------------------------------------------------------------------
# Native quantile baselines: sklearn's own linear QuantileRegressor, and
# GradientBoostingRegressor(loss="quantile") -- neither wraps another model.
# ---------------------------------------------------------------------------
def fit_predict_native_quantile(method, X_train, y_train, X_test, level):
    low_q = (1 - level / 100) / 2
    high_q = 1 - low_q
    if method == "sklearn_QuantileRegressor":
        m_low = SkQuantileRegressor(quantile=low_q, alpha=0.0, solver="highs")
        m_med = SkQuantileRegressor(quantile=0.5, alpha=0.0, solver="highs")
        m_high = SkQuantileRegressor(quantile=high_q, alpha=0.0, solver="highs")
    elif method == "GBM_quantile":
        m_low = GradientBoostingRegressor(loss="quantile", alpha=low_q, random_state=42)
        m_med = GradientBoostingRegressor(loss="quantile", alpha=0.5, random_state=42)
        m_high = GradientBoostingRegressor(loss="quantile", alpha=high_q, random_state=42)
    m_low.fit(X_train, y_train); m_med.fit(X_train, y_train); m_high.fit(X_train, y_train)
    lower, median, upper = m_low.predict(X_test), m_med.predict(X_test), m_high.predict(X_test)
    lower, upper = np.minimum(lower, upper), np.maximum(lower, upper)
    return lower, median, upper


native_results = []
for level in LEVELS:
    for ds_name, (X, y) in tqdm(DATASETS.items()):
        X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3, random_state=42)
        for method in ["sklearn_QuantileRegressor", "GBM_quantile"]:
            t0 = time.time()
            lower, median, upper = fit_predict_native_quantile(method, X_train, y_train, X_test, level)
            cov, width = coverage_and_width(y_test, lower, upper)
            wink = winkler_score(y_test, lower, upper, level=level)
            mae = np.mean(np.abs(y_test - median))
            native_results.append({"level": level, "dataset": ds_name, "method": method,
                                    "coverage": cov, "avg_interval_width": width,
                                    "winkler_score": wink, "median_MAE": mae,
                                    "time_s": time.time() - t0})

native = pd.DataFrame(native_results)
native.to_csv("native_quantile_baselines.csv", index=False)
print(native.groupby(["level", "method"])["coverage"].agg(["mean", "median", "min", "max"]).round(3))
100%|██████████| 6/6 [00:18<00:00,  3.16s/it]
100%|██████████| 6/6 [00:20<00:00,  3.49s/it]

                                 mean  median  min  max
level method
80    GBM_quantile               0.69    0.69 0.61 0.77
      sklearn_QuantileRegressor  0.76    0.77 0.67 0.80
95    GBM_quantile               0.92    0.92 0.86 1.00
      sklearn_QuantileRegressor  0.87    0.91 0.67 0.93
Headline result: it’s a solid technique, most of the time
Restricting to the runs that didn’t misbehave (more on that below), let’s check
how often QuantileRegressor’s median coverage landed within 3 percentage points
of the target level, and compare method families head-to-head against the native
baselines.
ok = full_sweep[full_sweep.status == "ok"].copy()
ok["collapsed"] = ok["avg_interval_width"] < 1e-6

agg = ok.groupby(["level", "method", "estimator"]).agg(
    mean_cov=("coverage", "mean"), median_cov=("coverage", "median"), min_cov=("coverage", "min"),
    n=("coverage", "count"), n_collapsed=("collapsed", "sum")
).reset_index()
agg.to_csv("full_sweep_estimator_summary.csv", index=False)

qr = agg[agg.method.str.startswith("QR:")]
for level in LEVELS:
    target = level / 100
    sub = qr[(qr.level == level) & (qr.n_collapsed == 0)].copy()
    sub["gap"] = (sub["median_cov"] - target).abs()
    good = sub[sub["gap"] <= 0.03]
    print(f"Level {level}%: {len(good)} of {len(sub)} non-collapsing (scoring, estimator) "
          f"pairs land within 3pts of target on median coverage ({len(good)/len(sub):.0%})")
Level 80%: 126 of 173 non-collapsing (scoring, estimator) pairs land within 3pts of target on median coverage (73%)
Level 95%: 133 of 173 non-collapsing (scoring, estimator) pairs land within 3pts of target on median coverage (77%)
# Safe estimators: never collapsed under any QuantileRegressor scoring mode
never_collapse = qr.groupby("estimator")["n_collapsed"].sum()
SAFE_ESTIMATORS = sorted(never_collapse[never_collapse == 0].index.tolist())
RISKY_ESTIMATORS = sorted(never_collapse[never_collapse > 0].index.tolist())
print(f"{len(SAFE_ESTIMATORS)} estimators NEVER collapse under any QuantileRegressor scoring mode:")
print(SAFE_ESTIMATORS)
print(f"\n{len(RISKY_ESTIMATORS)} estimators collapse under at least one scoring mode/level/dataset:")
print(RISKY_ESTIMATORS)
34 estimators NEVER collapse under any QuantileRegressor scoring mode:
['ARDRegression', 'BaggingRegressor', 'BayesianRidge', 'DummyRegressor', 'ElasticNet', 'ElasticNetCV', 'GammaRegressor', 'HuberRegressor', 'KNeighborsRegressor', 'KernelRidge', 'Lars', 'LarsCV', 'Lasso', 'LassoCV', 'LassoLars', 'LassoLarsCV', 'LassoLarsIC', 'LinearRegression', 'LinearSVR', 'NuSVR', 'OrthogonalMatchingPursuit', 'OrthogonalMatchingPursuitCV', 'PLSRegression', 'PassiveAggressiveRegressor', 'PoissonRegressor', 'QuantileRegressor', 'RANSACRegressor', 'RadiusNeighborsRegressor', 'Ridge', 'RidgeCV', 'SGDRegressor', 'SVR', 'TheilSenRegressor', 'TweedieRegressor']

4 estimators collapse under at least one scoring mode/level/dataset:
['AdaBoostRegressor', 'DecisionTreeRegressor', 'ExtraTreeRegressor', 'GaussianProcessRegressor']
# Method-family comparison: average coverage across the *safe* estimators only,
# so the trees/GP collapse doesn't distort the picture -- compared against the
# two native quantile baselines.
rows = []
for level in LEVELS:
    for method in ["QR:residuals", "QR:conformal", "PredictionInterval"]:
        sub = agg[(agg.level == level) & (agg.method == method) & (agg.estimator.isin(SAFE_ESTIMATORS))]
        rows.append({"level": level, "method": method, "mean_cov": sub.mean_cov.mean()})
    for method in ["sklearn_QuantileRegressor", "GBM_quantile"]:
        sub = native[(native.level == level) & (native.method == method)]
        rows.append({"level": level, "method": method, "mean_cov": sub.coverage.mean()})

family = pd.DataFrame(rows)
family.to_csv("method_family_comparison.csv", index=False)

labels_map = {
    "QR:residuals": "nnetsauce QuantileRegressor\n(residuals scoring)",
    "QR:conformal": "nnetsauce QuantileRegressor\n(conformal scoring)",
    "PredictionInterval": "nnetsauce PredictionInterval\n(splitconformal)",
    "sklearn_QuantileRegressor": "sklearn QuantileRegressor\n(native, linear)",
    "GBM_quantile": "GradientBoosting\n(native, quantile loss)",
}
methods_order = ["QR:residuals", "QR:conformal", "PredictionInterval", "sklearn_QuantileRegressor", "GBM_quantile"]
colors = ["#4C72B0", "#8CA8D8", "#DD8452", "#55A868", "#C44E52"]

fig, axes = plt.subplots(1, 2, figsize=(11, 4.5), sharey=True)
for ax, level, target in zip(axes, LEVELS, [l / 100 for l in LEVELS]):
    sub = family[family.level == level].set_index("method").loc[methods_order]
    ax.bar(range(len(methods_order)), sub["mean_cov"], color=colors)
    ax.axhline(target, color="black", linestyle="--", linewidth=1, label=f"target ({int(target*100)}%)")
    ax.set_xticks(range(len(methods_order)))
    ax.set_xticklabels([labels_map[m] for m in methods_order], rotation=30, ha="right", fontsize=8)
    ax.set_title(f"Target coverage: {int(target*100)}%")
    ax.set_ylim(0, 1.05)
    ax.legend(fontsize=8, loc="lower right")
axes[0].set_ylabel("Mean empirical coverage")
plt.tight_layout()
plt.savefig("coverage_comparison.png", dpi=150)
plt.show()

print(family.round(3).to_string(index=False))
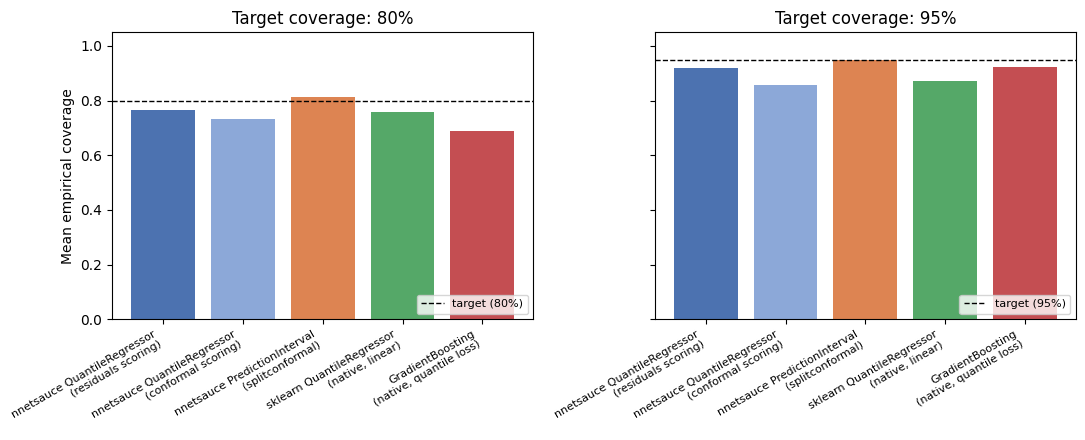
 level                    method  mean_cov
    80              QR:residuals      0.77
    80              QR:conformal      0.73
    80        PredictionInterval      0.81
    80 sklearn_QuantileRegressor      0.76
    80              GBM_quantile      0.69
    95              QR:residuals      0.92
    95              QR:conformal      0.86
    95        PredictionInterval      0.95
    95 sklearn_QuantileRegressor      0.87
    95              GBM_quantile      0.92
A few things stand out:
PredictionInterval(splitconformal) was the best-calibrated method in our grid, at both targets. It computes a single calibration-residual quantile and never re-optimizes against data the model has already seen, which turns out to matter a lot (see next section).QuantileRegressorwithscoring="residuals"essentially matches scikit-learn’s own native linearQuantileRegressorat the 80% target and clearly beats it at the 95% target (where the native version was dragged down by the 20-rowlinneruddataset).- Gradient-boosted quantile regression undercovered the most at the 80%
target — likely because with unregularized default hyperparameters,
GradientBoostingRegressorstarts overfitting each quantile individually rather than producing a coherent interval. It did comparatively better at 95%.
The takeaway isn’t “throw away purpose-built quantile regressors.” It’s that a model-agnostic wrapper around an off-the-shelf regressor is a competitive alternative when you want interval estimates from a model family that doesn’t have a native quantile-loss variant (say, a Support Vector Regressor, or a Bayesian linear model) — and it costs nothing extra to try.
The catch: it fails predictably, and only for one kind of model
Here’s the part worth being careful about. Let’s find every run where the predicted interval collapsed to (near) zero width.
collapsed = ok[ok.avg_interval_width < 1e-6]
piv = collapsed[collapsed.method != "PredictionInterval"].pivot_table(
    index="estimator", columns="method", values="coverage", aggfunc="count", fill_value=0
)
risky_order = [e for e in ["DecisionTreeRegressor", "ExtraTreeRegressor",
                            "GaussianProcessRegressor", "AdaBoostRegressor"] if e in piv.index]
piv = piv.reindex(risky_order).fillna(0)
methods_order2 = [f"QR:{s}" for s in SCORINGS]
piv = piv[methods_order2]
print(piv.astype(int))
print(f"\nPredictionInterval collapsed count (out of {len(ok[ok.method=='PredictionInterval'])}):",
      len(ok[(ok.method == "PredictionInterval") & (ok.avg_interval_width < 1e-6)]))
method                    QR:predictions  QR:residuals  QR:conformal  \
estimator
DecisionTreeRegressor                 12            12            12
ExtraTreeRegressor                    12            12            12
GaussianProcessRegressor              10             9             9
AdaBoostRegressor                      0             0             2

method                    QR:studentized  QR:conformal-studentized
estimator
DecisionTreeRegressor                 12                        12
ExtraTreeRegressor                    12                        12
GaussianProcessRegressor               9                         9
AdaBoostRegressor                      0                         2

PredictionInterval collapsed count (out of 448): 0
fig, ax = plt.subplots(figsize=(8, 4.5))
bottom = np.zeros(len(piv))
set2 = plt.cm.Set2(np.linspace(0, 1, len(methods_order2)))
for m, c in zip(methods_order2, set2):
    ax.bar(piv.index, piv[m], bottom=bottom, label=m, color=c)
    bottom += piv[m].values
ax.set_ylabel("# collapsed runs (out of 12 = 6 datasets x 2 levels)")
ax.set_title("QuantileRegressor: zero-width interval collapse, by base estimator and scoring mode")
ax.legend(fontsize=8, ncol=2)
plt.xticks(rotation=15, ha="right")
plt.tight_layout()
plt.savefig("collapse_chart.png", dpi=150)
plt.show()
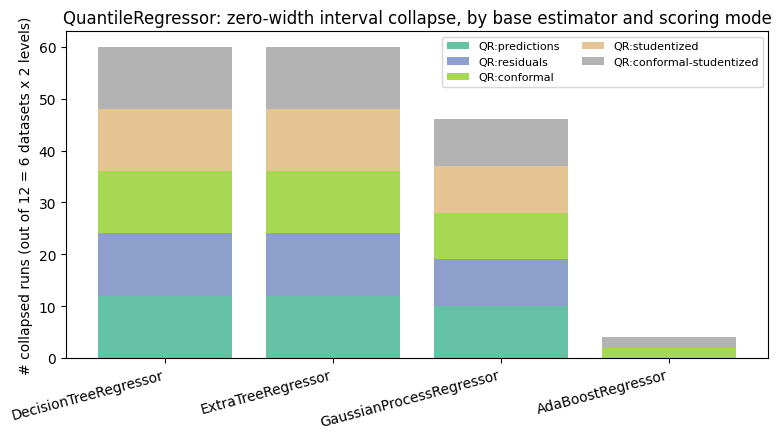
DecisionTreeRegressor and ExtraTreeRegressor collapsed on every single
run (12 out of 12 — all 6 datasets, both levels), regardless of which of the 5
scoring strategies was used. GaussianProcessRegressor collapsed on 9–10 out of
12 runs. AdaBoostRegressor collapsed occasionally, only under the two
conformal* scoring modes.
The mechanism is the same in every case, and it isn’t specific to any one
scoring strategy — it happens because QuantileRegressor optimizes its
interval-width multiplier by minimizing pinball loss on data the base model
has already been fit on (either the full training set, for
predictions/residuals/studentized, or a calibration split the model gets
re-fit to, for conformal/conformal-studentized). An unconstrained decision
tree, or a Gaussian process with a noiseless kernel, can memorize that data
almost perfectly. Once training residuals are ~0, the optimizer correctly
notices that a zero-width interval already achieves close to the minimum
possible pinball loss — and it collapses the interval accordingly, regardless
of whether the scale factor being multiplied is a residual standard deviation,
a prediction magnitude, or the target’s own standard deviation.
The practical rule this suggests: don’t pair QuantileRegressor with base
estimators capable of near-perfect interpolation of their own fitting data —
unconstrained trees and noiseless GPs, specifically. Every other estimator we
tested — the entire linear family, SVR/NuSVR/LinearSVR, KernelRidge,
KNeighborsRegressor, RANSACRegressor, TheilSenRegressor, the GLMs,
Bagging, PassiveAggressiveRegressor, SGDRegressor — never collapsed
once, across any scoring mode, dataset, or coverage level.
Best performers at each target level
Within the safe estimators, here’s what came closest to nominal coverage (median across the 6 datasets), along with the worst-case dataset for each — because a good median can still hide a bad outlier, and we don’t want to bury that in an average.
for level in LEVELS:
    target = level / 100
    sub = qr[(qr.level == level) & (qr.n_collapsed == 0)].copy()
    sub["gap"] = (sub["median_cov"] - target).abs()
    print(f"=== {level}% target: top 5 by |median coverage - target| ===")
    top5 = sub.sort_values("gap").head(5)[["method", "estimator", "mean_cov", "median_cov", "min_cov"]]
    print(top5.round(3).to_string(index=False))
    print()
=== 80% target: top 5 by |median coverage - target| ===
                  method                  estimator  mean_cov  median_cov  min_cov
            QR:conformal              BayesianRidge      0.77        0.80     0.67
            QR:conformal                KernelRidge      0.76        0.80     0.50
            QR:conformal                       Lars      0.75        0.80     0.50
QR:conformal-studentized              BayesianRidge      0.77        0.80     0.67
          QR:studentized PassiveAggressiveRegressor      0.82        0.80     0.74

=== 95% target: top 5 by |median coverage - target| ===
        method        estimator  mean_cov  median_cov  min_cov
  QR:residuals       ElasticNet      0.93        0.95     0.83
QR:studentized       ElasticNet      0.93        0.95     0.83
  QR:residuals TweedieRegressor      0.94        0.95     0.83
  QR:conformal    BayesianRidge      0.91        0.95     0.67
  QR:residuals    PLSRegression      0.93        0.95     0.83
The worst-case column (min_cov) is a useful sanity check: even the
best-calibrated combinations here have at least one dataset where coverage
drops well below target — usually linnerud, which has only 6 test
observations after the split, so treat those specific numbers as noisy rather
than damning. It’s a reminder that “good on average” and “reliable everywhere”
are different claims, worth checking separately rather than folding into one
number.
Practical guidance
Putting it together, if you’re deciding how to get prediction intervals out of
an arbitrary scikit-learn (or R, via nnetsauce_r) regressor:
- Default to
scoring="residuals"over"conformal"if you want the simplest behavior — it doesn’t need a train/calibration split, and it performed as well or better in this benchmark."studentized"and"conformal-studentized"tracked their non-studentized siblings closely enough (coverage correlation ≥0.96 in the full grid) that they add little beyond redundancy. - Reach for
PredictionInterval(method="splitconformal")if you want the most robust option and don’t need the flexibility of the 5 scoring strategies — it was the best-calibrated method here and never collapsed on any estimator. - Avoid pairing either wrapper with unconstrained trees or noiseless
Gaussian processes. If you need a tree-based interval,
RandomForestRegressor,BaggingRegressor, orAdaBoostRegressor(mostly) sidestep the issue since they don’t interpolate the data as tightly as a single unconstrained tree. - Check coverage on a genuine holdout, per use case, before trusting the number — “good on average across 6 datasets” is a benchmarking convenience, not a guarantee for your specific one.
Reproducibility
Every run in this notebook used default hyperparameters — no GridSearchCV, no
manual tuning — so the numbers reflect what you’d see trying this out of the
box. Re-running this notebook end-to-end reproduces every table and chart
above from scratch (data is downloaded fresh at runtime); the intermediate
CSVs (full_sweep_results.csv, full_sweep_estimator_summary.csv,
native_quantile_baselines.csv, method_family_comparison.csv) are also
written to disk if you want to explore further without re-running the sweep.
Benchmarked: nnetsauce QuantileRegressor and PredictionInterval
(source,
source),
the R wrapper
(source),
against scikit-learn’s QuantileRegressor and GradientBoostingRegressor(loss="quantile").
For attribution, please cite this work as:
T. Moudiki (2026-09-14). Model-agnostic prediction intervals in Python and R: does nnetsauce's QuantileRegressor hold up?. Retrieved from https://thierrymoudiki.github.io/blog/2026/09/14/r/python/quantileregressor-benchmark
BibTeX citation (remove empty spaces)
        @misc{ tmoudiki20260914,
          author = { T. Moudiki },
          title = { Model-agnostic prediction intervals in Python and R: does nnetsauce's QuantileRegressor hold up? },
          url = { https://thierrymoudiki.github.io/blog/2026/09/14/r/python/quantileregressor-benchmark },
          year = { 2026 } }

Previous publications
- Model-agnostic prediction intervals in Python and R: does nnetsauce's QuantileRegressor hold up? Sep 14, 2026
- ahead (Time Series Forecasting with uncertainty quantification) gets a lot faster to install: most dependencies are now optional Sep 8, 2026
- Skip the R/Python runtime: fast tabular dashboards with Observable Framework Aug 31, 2026
- PCARVFL vs CTGAN for synthetic tabular data generation on an insurance pricing dataset Aug 22, 2026
- 'Zero-Shot Probabilistic Stock Returns Forecasting with Pretrained RVFL Networks' accepted at COPA 2026 (and to appear in the Proceedings of Machine Learning Research) Aug 15, 2026
- 'PCARVFLSimulator': a GAN-like tabular data synthesizer built from PCA scores, a Random Vector Functional-Link network, and residuals bootstrapping Aug 10, 2026
- 'garchf': GARCH probabilistic forecasting with package 'forecast'-style interface (and 'rugarch' under the hood) Aug 1, 2026
- GPopt for R: Bayesian and conformal optimization of black-box functions and hyperparameter tuning Jul 26, 2026
- My last R posts: How conformalization helps weak models, fast conformal prediction with jackknife+ (and no refitting), and sklearn in R Jul 13, 2026
- Natively Interpretable Boosting Jul 12, 2026
- Fast conformal prediction (no refitting) for some Machine Learning models via closed-form jackknife plus Jun 27, 2026
- Using scikit-learn models in R easily with the tisthemachinelearner package Jun 21, 2026
- No-Code Machine Learning in Excel with the Techtonique API Jun 14, 2026
- How Conformal Prediction Makes Linear Models Good Enough — An Example Using R Package mlS3 Jun 7, 2026
- Techtonique dot net, the Machine Learning web API, is back online (but more like a passion project for now) May 31, 2026
- Conformalized TabICL: Prediction Intervals for a State-Of-The-Art Tabular Foundation Model in Python and R May 21, 2026
- Conformalized TabPFN: Prediction Intervals for a Pretrained Transformer for Tabular Data in Python and R May 17, 2026
- Probabilistic Time Series Cross-Validation with R package crossvalidation May 16, 2026
- One interface, (Almost) Every Classifier (and Regressor): unifiedml v0.3.0 May 9, 2026
- You Don't Need to Learn All the Weights on tabular data: The Case for rvflnet (a nonlinear expressive glmnet) on regression, classification and survival analysis May 2, 2026
- Survival analysis with sklearn, glmnet, keras, pytorch, lightgbm, xgboost, nnetsauce, mlsauce Part 2 Apr 28, 2026
- Any Sklearn Regressor as a Survival Model — Does It Actually Work? Benchmarking vs Established Packages Apr 26, 2026
- Conformal Optimization Beats Bayesian Optimization, Optuna and Random Search on 72 classification Datasets Apr 19, 2026
- `mlS3` — A Unified S3 Machine Learning Interface in R Apr 12, 2026
- One interface, (Almost) Every Classifier: unifiedml v0.2.1 Apr 4, 2026
- Techtonique dot net is down until further notice Apr 1, 2026
- Explaining Time-Series Forecasts with Sensitivity Analysis (ahead::dynrmf and external regressors) Mar 29, 2026
- Python version of 'Option pricing using time series models as market price of risk Pt.3' Mar 22, 2026
- Option pricing using time series models as market price of risk Pt.3 Mar 16, 2026
- Explaining Time-Series Forecasts with Exact Shapley Values (ahead::dynrmf with external regressors applied to scenarios) Mar 8, 2026
- My Presentation at Risk 2026: Lightweight Transfer Learning for Financial Forecasting Mar 1, 2026
- nnetsauce with and without jax for GPU acceleration Feb 23, 2026
- Understanding Boosted Configuration Networks (combined neural networks and boosting): An Intuitive Guide Through Their Hyperparameters Feb 16, 2026
- R version of Python package survivalist, for model-agnostic survival analysis Feb 9, 2026
- Presenting Lightweight Transfer Learning for Financial Forecasting (Risk 2026) Feb 4, 2026
- Option pricing using time series models as market price of risk Feb 1, 2026
- Enhancing Time Series Forecasting (ahead::ridge2f) with Attention-Based Context Vectors (ahead::contextridge2f) Jan 31, 2026
- Overfitting and scaling (on GPU T4) tests on nnetsauce.CustomRegressor Jan 29, 2026
- Beyond Cross-validation: Hyperparameter Optimization via Generalization Gap Modeling Jan 25, 2026
- GPopt for Machine Learning (hyperparameters' tuning) Jan 21, 2026
- rtopy: an R to Python bridge -- novelties Jan 8, 2026
- Python examples for 'Beyond Nelson-Siegel and splines: A model- agnostic Machine Learning framework for discount curve calibration, interpolation and extrapolation' Jan 3, 2026
- Forecasting benchmark: Dynrmf (a new serious competitor in town) vs Theta Method on M-Competitions and Tourism competitition Jan 1, 2026
- Finally figured out a way to port python packages to R using uv and reticulate: example with nnetsauce Dec 17, 2025
- Overfitting Random Fourier Features: Universal Approximation Property Dec 13, 2025
- Counterfactual Scenario Analysis with ahead::ridge2f Dec 11, 2025
- Zero-Shot Probabilistic Time Series Forecasting with TabPFN 2.5 and nnetsauce Dec 10, 2025
- ARIMA Pricing: Semi-Parametric Market price of risk for Risk-Neutral Pricing (code + preprint) Dec 7, 2025
- Analyzing Paper Reviews with LLMs: I Used ChatGPT, DeepSeek, Qwen, Mistral, Gemini, and Claude (and you should too + publish the analysis) Dec 3, 2025
- tisthemachinelearner: New Workflow with uv for R Integration of scikit-learn Dec 1, 2025
- (ICYMI) RPweave: Unified R + Python + LaTeX System using uv Nov 21, 2025
- unifiedml: A Unified Machine Learning Interface for R, is now on CRAN + Discussion about AI replacing humans Nov 16, 2025
- Context-aware Theta forecasting Method: Extending Classical Time Series Forecasting with Machine Learning Nov 13, 2025
- unifiedml in R: A Unified Machine Learning Interface Nov 5, 2025
- Deterministic Shift Adjustment in Arbitrage-Free Pricing (historical to risk-neutral short rates) Oct 28, 2025
- New instantaneous short rates models with their deterministic shift adjustment, for historical and risk-neutral simulation Oct 27, 2025
- RPweave: Unified R + Python + LaTeX System using uv Oct 19, 2025
- GAN-like Synthetic Data Generation Examples (on univariate, multivariate distributions, digits recognition, Fashion-MNIST, stock returns, and Olivetti faces) with DistroSimulator Oct 19, 2025
- R port of llama2.c Oct 9, 2025
- Native uncertainty quantification for time series with NGBoost Oct 8, 2025
- NGBoost (Natural Gradient Boosting) for Regression, Classification, Time Series forecasting and Reserving Oct 6, 2025
- Real-time pricing with a pretrained probabilistic stock return model Oct 1, 2025
- Combining any model with GARCH(1,1) for probabilistic stock forecasting Sep 23, 2025
- Generating Synthetic Data with R-vine Copulas using esgtoolkit in R Sep 21, 2025
- Reimagining Equity Solvency Capital Requirement Approximation (one of my Master's Thesis subjects): From Bilinear Interpolation to Probabilistic Machine Learning Sep 16, 2025
- Transfer Learning using ahead::ridge2f on synthetic stocks returns Pt.2: synthetic data generation Sep 9, 2025
- Transfer Learning using ahead::ridge2f on synthetic stocks returns Sep 8, 2025
- I'm supposed to present 'Conformal Predictive Simulations for Univariate Time Series' at COPA CONFERENCE 2025 in London... Sep 4, 2025
- external regressors in ahead::dynrmf's interface for Machine learning forecasting Sep 1, 2025
- Another interesting decision, now for 'Beyond Nelson-Siegel and splines: A model-agnostic Machine Learning framework for discount curve calibration, interpolation and extrapolation' Aug 20, 2025
- Boosting any randomized based learner for regression, classification and univariate/multivariate time series forcasting Jul 26, 2025
- New nnetsauce version with CustomBackPropRegressor (CustomRegressor with Backpropagation) and ElasticNet2Regressor (Ridge2 with ElasticNet regularization) Jul 15, 2025
- mlsauce (home to a model-agnostic gradient boosting algorithm) can now be installed from PyPI. Jul 10, 2025
- A user-friendly graphical interface to techtonique dot net's API (will eventually contain graphics). Jul 8, 2025
- Calling =TECHTO_MLCLASSIFICATION for Machine Learning supervised CLASSIFICATION in Excel is just a matter of copying and pasting Jul 7, 2025
- Calling =TECHTO_MLREGRESSION for Machine Learning supervised regression in Excel is just a matter of copying and pasting Jul 6, 2025
- Calling =TECHTO_RESERVING and =TECHTO_MLRESERVING for claims triangle reserving in Excel is just a matter of copying and pasting Jul 5, 2025
- Calling =TECHTO_SURVIVAL for Survival Analysis in Excel is just a matter of copying and pasting Jul 4, 2025
- Calling =TECHTO_SIMULATION for Stochastic Simulation in Excel is just a matter of copying and pasting Jul 3, 2025
- Calling =TECHTO_FORECAST for forecasting in Excel is just a matter of copying and pasting Jul 2, 2025
- Random Vector Functional Link (RVFL) artificial neural network with 2 regularization parameters successfully used for forecasting/synthetic simulation in professional settings: Extensions (including Bayesian) Jul 1, 2025
- R version of 'Backpropagating quasi-randomized neural networks' Jun 24, 2025
- Backpropagating quasi-randomized neural networks Jun 23, 2025
- Beyond ARMA-GARCH: leveraging any statistical model for volatility forecasting Jun 21, 2025
- Stacked generalization (Machine Learning model stacking) + conformal prediction for forecasting with ahead::mlf Jun 18, 2025
- An Overfitting dilemma: XGBoost Default Hyperparameters vs GenericBooster + LinearRegression Default Hyperparameters Jun 14, 2025
- Programming language-agnostic reserving using RidgeCV, LightGBM, XGBoost, and ExtraTrees Machine Learning models Jun 13, 2025
- Free R, Python and SQL editors in techtonique dot net Jun 9, 2025
- Beyond Nelson-Siegel and splines: A model-agnostic Machine Learning framework for discount curve calibration, interpolation and extrapolation Jun 7, 2025
- scikit-learn, glmnet, xgboost, lightgbm, pytorch, keras, nnetsauce in probabilistic Machine Learning (for longitudinal data) Reserving (work in progress) Jun 6, 2025
- R version of Probabilistic Machine Learning (for longitudinal data) Reserving (work in progress) Jun 5, 2025
- Probabilistic Machine Learning (for longitudinal data) Reserving (work in progress) Jun 4, 2025
- Python version of Beyond ARMA-GARCH: leveraging model-agnostic Quasi-Randomized networks and conformal prediction for nonparametric probabilistic stock forecasting (ML-ARCH) Jun 3, 2025
- Beyond ARMA-GARCH: leveraging model-agnostic Machine Learning and conformal prediction for nonparametric probabilistic stock forecasting (ML-ARCH) Jun 2, 2025
- Permutations and SHAPley values for feature importance in techtonique dot net's API (with R + Python + the command line) Jun 1, 2025
- Which patient is going to survive longer? Another guide to using techtonique dot net's API (with R + Python + the command line) for survival analysis May 31, 2025
- A Guide to Using techtonique.net's API and rush for simulating and plotting Stochastic Scenarios May 30, 2025
- Simulating Stochastic Scenarios with Diffusion Models: A Guide to Using techtonique.net's API for the purpose May 29, 2025
- Will my apartment in 5th avenue be overpriced or not? Harnessing the power of www.techtonique.net (+ xgboost, lightgbm, catboost) to find out May 28, 2025
- How long must I wait until something happens: A Comprehensive Guide to Survival Analysis via an API May 27, 2025
- Harnessing the Power of techtonique.net: A Comprehensive Guide to Machine Learning Classification via an API May 26, 2025
- Quantile regression with any regressor -- Examples with RandomForestRegressor, RidgeCV, KNeighborsRegressor May 20, 2025
- Survival stacking: survival analysis translated as supervised classification in R and Python May 5, 2025
- 'Bayesian' optimization of hyperparameters in a R machine learning model using the bayesianrvfl package Apr 25, 2025
- A lightweight interface to scikit-learn in R: Bayesian and Conformal prediction Apr 21, 2025
- A lightweight interface to scikit-learn in R Pt.2: probabilistic time series forecasting in conjunction with ahead::dynrmf Apr 20, 2025
- Extending the Theta forecasting method to GLMs, GAMs, GLMBOOST and attention: benchmarking on Tourism, M1, M3 and M4 competition data sets (28000 series) Apr 14, 2025
- Extending the Theta forecasting method to GLMs and attention Apr 8, 2025
- Nonlinear conformalized Generalized Linear Models (GLMs) with R package 'rvfl' (and other models) Mar 31, 2025
- Probabilistic Time Series Forecasting (predictive simulations) in Microsoft Excel using Python, xlwings lite and www.techtonique.net Mar 28, 2025
- Conformalize (improved prediction intervals and simulations) any R Machine Learning model with misc::conformalize Mar 25, 2025
- My poster for the 18th FINANCIAL RISKS INTERNATIONAL FORUM by Institut Louis Bachelier/Fondation du Risque/Europlace Institute of Finance Mar 19, 2025
- Interpretable probabilistic kernel ridge regression using Matérn 3/2 kernels Mar 16, 2025
- (News from) Probabilistic Forecasting of univariate and multivariate Time Series using Quasi-Randomized Neural Networks (Ridge2) and Conformal Prediction Mar 9, 2025
- Word-Online: re-creating Karpathy's char-RNN (with supervised linear online learning of word embeddings) for text completion Mar 8, 2025
- CRAN-like repository for most recent releases of Techtonique's R packages Mar 2, 2025
- Presenting 'Online Probabilistic Estimation of Carbon Beta and Carbon Shapley Values for Financial and Climate Risk' at Institut Louis Bachelier Feb 27, 2025
- Web app with DeepSeek R1 and Hugging Face API for chatting Feb 23, 2025
- tisthemachinelearner: A Lightweight interface to scikit-learn with 2 classes, Classifier and Regressor (in Python and R) Feb 17, 2025
- R version of survivalist: Probabilistic model-agnostic survival analysis using scikit-learn, xgboost, lightgbm (and conformal prediction) Feb 12, 2025
- Model-agnostic global Survival Prediction of Patients with Myeloid Leukemia in QRT/Gustave Roussy Challenge (challengedata.ens.fr): Python's survivalist Quickstart Feb 10, 2025
- A simple test of the martingale hypothesis in esgtoolkit Feb 3, 2025
- Command Line Interface (CLI) for techtonique.net's API Jan 31, 2025
- Gradient-Boosting and Boostrap aggregating anything (alert: high performance): Part5, easier install and Rust backend Jan 27, 2025
- Just got a paper on conformal prediction REJECTED by International Journal of Forecasting despite evidence on 30,000 time series (and more). What's going on? Part2: 1311 time series from the Tourism competition Jan 20, 2025
- Techtonique is released! (with a tutorial in various programming languages and formats) Jan 14, 2025
- Univariate and Multivariate Probabilistic Forecasting with nnetsauce and TabPFN Jan 14, 2025
- Just got a paper on conformal prediction REJECTED by International Journal of Forecasting despite evidence on 30,000 time series (and more). What's going on? Jan 5, 2025
- Python and Interactive dashboard version of Stock price forecasting with Deep Learning: throwing power at the problem (and why it won't make you rich) Dec 31, 2024
- Stock price forecasting with Deep Learning: throwing power at the problem (and why it won't make you rich) Dec 29, 2024
- No-code Machine Learning Cross-validation and Interpretability in techtonique.net Dec 23, 2024
- survivalist: Probabilistic model-agnostic survival analysis using scikit-learn, glmnet, xgboost, lightgbm, pytorch, keras, nnetsauce and mlsauce Dec 15, 2024
- Model-agnostic 'Bayesian' optimization (for hyperparameter tuning) using conformalized surrogates in GPopt Dec 9, 2024
- You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTS Pt.2: Generic Gradient Boosting Dec 1, 2024
- You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTS Nov 24, 2024
- Unified interface and conformal prediction (calibrated prediction intervals) for R package forecast (and 'affiliates') Nov 23, 2024
- GLMNet in Python: Generalized Linear Models Nov 18, 2024
- Gradient-Boosting anything (alert: high performance): Part4, Time series forecasting Nov 10, 2024
- Predictive scenarios simulation in R, Python and Excel using Techtonique API Nov 3, 2024
- Chat with your tabular data in www.techtonique.net Oct 30, 2024
- Gradient-Boosting anything (alert: high performance): Part3, Histogram-based boosting Oct 28, 2024
- R editor and SQL console (in addition to Python editors) in www.techtonique.net Oct 21, 2024
- R and Python consoles + JupyterLite in www.techtonique.net Oct 15, 2024
- Gradient-Boosting anything (alert: high performance): Part2, R version Oct 14, 2024
- Gradient-Boosting anything (alert: high performance) Oct 6, 2024
- Benchmarking 30 statistical/Machine Learning models on the VN1 Forecasting -- Accuracy challenge Oct 4, 2024
- Automated random variable distribution inference using Kullback-Leibler divergence and simulating best-fitting distribution Oct 2, 2024
- Forecasting in Excel using Techtonique's Machine Learning APIs under the hood Sep 30, 2024
- Techtonique web app for data-driven decisions using Mathematics, Statistics, Machine Learning, and Data Visualization Sep 25, 2024
- Parallel for loops (Map or Reduce) + New versions of nnetsauce and ahead Sep 16, 2024
- Adaptive (online/streaming) learning with uncertainty quantification using Polyak averaging in learningmachine Sep 10, 2024
- New versions of nnetsauce and ahead Sep 9, 2024
- Prediction sets and prediction intervals for conformalized Auto XGBoost, Auto LightGBM, Auto CatBoost, Auto GradientBoosting Sep 2, 2024
- Quick/automated R package development workflow (assuming you're using macOS or Linux) Part2 Aug 30, 2024
- R package development workflow (assuming you're using macOS or Linux) Aug 27, 2024
- A new method for deriving a nonparametric confidence interval for the mean Aug 26, 2024
- Conformalized adaptive (online/streaming) learning using learningmachine in Python and R Aug 19, 2024
- Bayesian (nonlinear) adaptive learning Aug 12, 2024
- Auto XGBoost, Auto LightGBM, Auto CatBoost, Auto GradientBoosting Aug 5, 2024
- Copulas for uncertainty quantification in time series forecasting Jul 28, 2024
- Forecasting uncertainty: sequential split conformal prediction + Block bootstrap (web app) Jul 22, 2024
- learningmachine for Python (new version) Jul 15, 2024
- learningmachine v2.0.0: Machine Learning with explanations and uncertainty quantification Jul 8, 2024
- My presentation at ISF 2024 conference (slides with nnetsauce probabilistic forecasting news) Jul 3, 2024
- 10 uncertainty quantification methods in nnetsauce forecasting Jul 1, 2024
- Forecasting with XGBoost embedded in Quasi-Randomized Neural Networks Jun 24, 2024
- Forecasting Monthly Airline Passenger Numbers with Quasi-Randomized Neural Networks Jun 17, 2024
- Automated hyperparameter tuning using any conformalized surrogate Jun 9, 2024
- Recognizing handwritten digits with Ridge2Classifier Jun 3, 2024
- Forecasting the Economy May 27, 2024
- A detailed introduction to Deep Quasi-Randomized 'neural' networks May 19, 2024
- Probability of receiving a loan; using learningmachine May 12, 2024
- mlsauce's `v0.18.2`: various examples and benchmarks with dimension reduction May 6, 2024
- mlsauce's `v0.17.0`: boosting with Elastic Net, polynomials and heterogeneity in explanatory variables Apr 29, 2024
- mlsauce's `v0.13.0`: taking into account inputs heterogeneity through clustering Apr 21, 2024
- mlsauce's `v0.12.0`: prediction intervals for LSBoostRegressor Apr 15, 2024
- Conformalized predictive simulations for univariate time series on more than 250 data sets Apr 7, 2024
- learningmachine v1.1.2: for Python Apr 1, 2024
- learningmachine v1.0.0: prediction intervals around the probability of the event 'a tumor being malignant' Mar 25, 2024
- Bayesian inference and conformal prediction (prediction intervals) in nnetsauce v0.18.1 Mar 18, 2024
- Multiple examples of Machine Learning forecasting with ahead Mar 11, 2024
- rtopy (v0.1.1): calling R functions in Python Mar 4, 2024
- ahead forecasting (v0.10.0): fast time series model calibration and Python plots Feb 26, 2024
- A plethora of datasets at your fingertips Part3: how many times do couples cheat on each other? Feb 19, 2024
- nnetsauce's introduction as of 2024-02-11 (new version 0.17.0) Feb 11, 2024
- Tuning Machine Learning models with GPopt's new version Part 2 Feb 5, 2024
- Tuning Machine Learning models with GPopt's new version Jan 29, 2024
- Subsampling continuous and discrete response variables Jan 22, 2024
- DeepMTS, a Deep Learning Model for Multivariate Time Series Jan 15, 2024
- A classifier that's very accurate (and deep) Pt.2: there are > 90 classifiers in nnetsauce Jan 8, 2024
- learningmachine: prediction intervals for conformalized Kernel ridge regression and Random Forest Jan 1, 2024
- A plethora of datasets at your fingertips Part2: how many times do couples cheat on each other? Descriptive analytics, interpretability and prediction intervals using conformal prediction Dec 25, 2023
- Diffusion models in Python with esgtoolkit (Part2) Dec 18, 2023
- Diffusion models in Python with esgtoolkit Dec 11, 2023
- Julia packaging at the command line Dec 4, 2023
- Quasi-randomized nnetworks in Julia, Python and R Nov 27, 2023
- A plethora of datasets at your fingertips Nov 20, 2023
- A classifier that's very accurate (and deep) Nov 12, 2023
- mlsauce version 0.8.10: Statistical/Machine Learning with Python and R Nov 5, 2023
- AutoML in nnetsauce (randomized and quasi-randomized nnetworks) Pt.2: multivariate time series forecasting Oct 29, 2023
- AutoML in nnetsauce (randomized and quasi-randomized nnetworks) Oct 22, 2023
- Version v0.14.0 of nnetsauce for R and Python Oct 16, 2023
- A diffusion model: G2++ Oct 9, 2023
- Diffusion models in ESGtoolkit + announcements Oct 2, 2023
- An infinity of time series forecasting models in nnetsauce (Part 2 with uncertainty quantification) Sep 25, 2023
- (News from) forecasting in Python with ahead (progress bars and plots) Sep 18, 2023
- Forecasting in Python with ahead Sep 11, 2023
- Risk-neutralize simulations Sep 4, 2023
- Comparing cross-validation results using crossval_ml and boxplots Aug 27, 2023
- Reminder Apr 30, 2023
- Did you ask ChatGPT about who you are? Apr 16, 2023
- A new version of nnetsauce (randomized and quasi-randomized 'neural' networks) Apr 2, 2023
- Simple interfaces to the forecasting API Nov 23, 2022
- A web application for forecasting in Python, R, Ruby, C#, JavaScript, PHP, Go, Rust, Java, MATLAB, etc. Nov 2, 2022
- Prediction intervals (not only) for Boosted Configuration Networks in Python Oct 5, 2022
- Boosted Configuration (neural) Networks Pt. 2 Sep 3, 2022
- Boosted Configuration (_neural_) Networks for classification Jul 21, 2022
- A Machine Learning workflow using Techtonique Jun 6, 2022
- Super Mario Bros © in the browser using PyScript May 8, 2022
- News from ESGtoolkit, ycinterextra, and nnetsauce Apr 4, 2022
- Explaining a Keras _neural_ network predictions with the-teller Mar 11, 2022
- New version of nnetsauce -- various quasi-randomized networks Feb 12, 2022
- A dashboard illustrating bivariate time series forecasting with `ahead` Jan 14, 2022
- Hundreds of Statistical/Machine Learning models for univariate time series, using ahead, ranger, xgboost, and caret Dec 20, 2021
- Forecasting with `ahead` (Python version) Dec 13, 2021
- Tuning and interpreting LSBoost Nov 15, 2021
- Time series cross-validation using `crossvalidation` (Part 2) Nov 7, 2021
- Fast and scalable forecasting with ahead::ridge2f Oct 31, 2021
- Automatic Forecasting with `ahead::dynrmf` and Ridge regression Oct 22, 2021
- Forecasting with `ahead` Oct 15, 2021
- Classification using linear regression Sep 26, 2021
- `crossvalidation` and random search for calibrating support vector machines Aug 6, 2021
- parallel grid search cross-validation using `crossvalidation` Jul 31, 2021
- `crossvalidation` on R-universe, plus a classification example Jul 23, 2021
- Documentation and source code for GPopt, a package for Bayesian optimization Jul 2, 2021
- Hyperparameters tuning with GPopt Jun 11, 2021
- A forecasting tool (API) with examples in curl, R, Python May 28, 2021
- Bayesian Optimization with GPopt Part 2 (save and resume) Apr 30, 2021
- Bayesian Optimization with GPopt Apr 16, 2021
- Compatibility of nnetsauce and mlsauce with scikit-learn Mar 26, 2021
- Explaining xgboost predictions with the teller Mar 12, 2021
- An infinity of time series models in nnetsauce Mar 6, 2021
- New activation functions in mlsauce's LSBoost Feb 12, 2021
- 2020 recap, Gradient Boosting, Generalized Linear Models, AdaOpt with nnetsauce and mlsauce Dec 29, 2020
- A deeper learning architecture in nnetsauce Dec 18, 2020
- Classify penguins with nnetsauce's MultitaskClassifier Dec 11, 2020
- Bayesian forecasting for uni/multivariate time series Dec 4, 2020
- Generalized nonlinear models in nnetsauce Nov 28, 2020
- Boosting nonlinear penalized least squares Nov 21, 2020
- Statistical/Machine Learning explainability using Kernel Ridge Regression surrogates Nov 6, 2020
- NEWS Oct 30, 2020
- A glimpse into my PhD journey Oct 23, 2020
- Submitting R package to CRAN Oct 16, 2020
- Simulation of dependent variables in ESGtoolkit Oct 9, 2020
- Forecasting lung disease progression Oct 2, 2020
- New nnetsauce Sep 25, 2020
- Technical documentation Sep 18, 2020
- A new version of nnetsauce, and a new Techtonique website Sep 11, 2020
- Back next week, and a few announcements Sep 4, 2020
- Explainable 'AI' using Gradient Boosted randomized networks Pt2 (the Lasso) Jul 31, 2020
- LSBoost: Explainable 'AI' using Gradient Boosted randomized networks (with examples in R and Python) Jul 24, 2020
- nnetsauce version 0.5.0, randomized neural networks on GPU Jul 17, 2020
- Maximizing your tip as a waiter (Part 2) Jul 10, 2020
- New version of mlsauce, with Gradient Boosted randomized networks and stump decision trees Jul 3, 2020
- Announcements Jun 26, 2020
- Parallel AdaOpt classification Jun 19, 2020
- Comments section and other news Jun 12, 2020
- Maximizing your tip as a waiter Jun 5, 2020
- AdaOpt classification on MNIST handwritten digits (without preprocessing) May 29, 2020
- AdaOpt (a probabilistic classifier based on a mix of multivariable optimization and nearest neighbors) for R May 22, 2020
- AdaOpt May 15, 2020
- Custom errors for cross-validation using crossval::crossval_ml May 8, 2020
- Documentation+Pypi for the `teller`, a model-agnostic tool for Machine Learning explainability May 1, 2020
- Encoding your categorical variables based on the response variable and correlations Apr 24, 2020
- Linear model, xgboost and randomForest cross-validation using crossval::crossval_ml Apr 17, 2020
- Grid search cross-validation using crossval Apr 10, 2020
- Documentation for the querier, a query language for Data Frames Apr 3, 2020
- Time series cross-validation using crossval Mar 27, 2020
- On model specification, identification, degrees of freedom and regularization Mar 20, 2020
- Import data into the querier (now on Pypi), a query language for Data Frames Mar 13, 2020
- R notebooks for nnetsauce Mar 6, 2020
- Version 0.4.0 of nnetsauce, with fruits and breast cancer classification Feb 28, 2020
- Create a specific feed in your Jekyll blog Feb 21, 2020
- Git/Github for contributing to package development Feb 14, 2020
- Feedback forms for contributing Feb 7, 2020
- nnetsauce for R Jan 31, 2020
- A new version of nnetsauce (v0.3.1) Jan 24, 2020
- ESGtoolkit, a tool for Monte Carlo simulation (v0.2.0) Jan 17, 2020
- Search bar, new year 2020 Jan 10, 2020
- 2019 Recap, the nnetsauce, the teller and the querier Dec 20, 2019
- Understanding model interactions with the `teller` Dec 13, 2019
- Using the `teller` on a classifier Dec 6, 2019
- Benchmarking the querier's verbs Nov 29, 2019
- Composing the querier's verbs for data wrangling Nov 22, 2019
- Comparing and explaining model predictions with the teller Nov 15, 2019
- Tests for the significance of marginal effects in the teller Nov 8, 2019
- Introducing the teller Nov 1, 2019
- Introducing the querier Oct 25, 2019
- Prediction intervals for nnetsauce models Oct 18, 2019
- Using R in Python for statistical learning/data science Oct 11, 2019
- Model calibration with `crossval` Oct 4, 2019
- Bagging in the nnetsauce Sep 25, 2019
- Adaboost learning with nnetsauce Sep 18, 2019
- Change in blog's presentation Sep 4, 2019
- nnetsauce on Pypi Jun 5, 2019
- More nnetsauce (examples of use) May 9, 2019
- nnetsauce Mar 13, 2019
- crossval Mar 13, 2019
- test Mar 10, 2019
Comments powered by Talkyard.